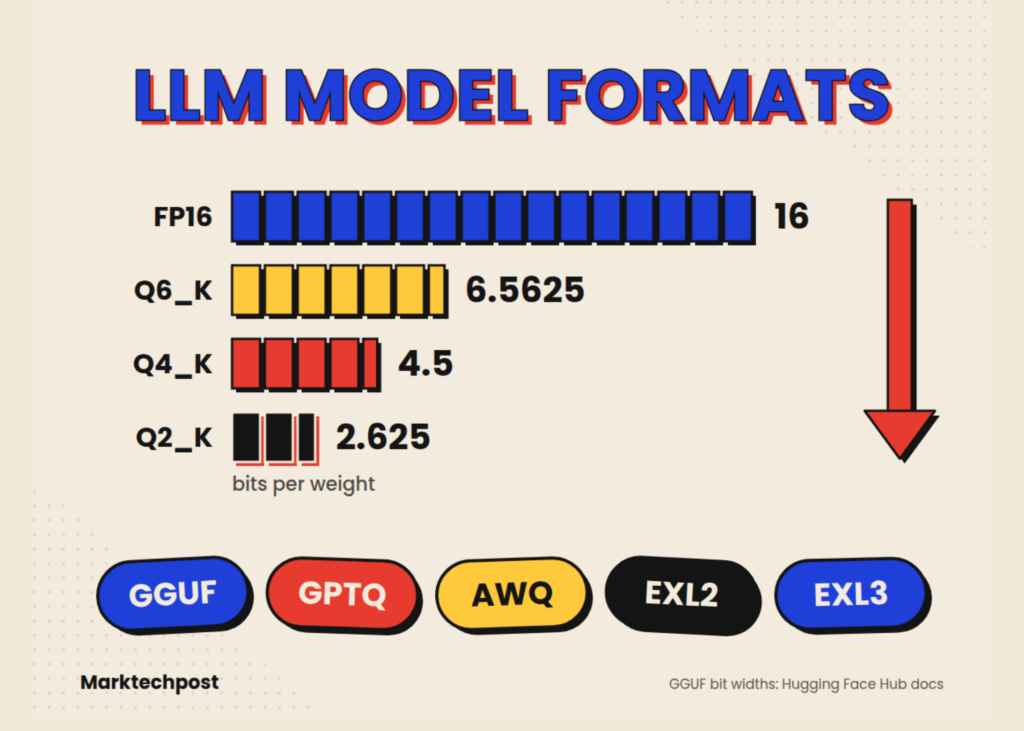
Confusion about large language model formats stems from mixing two distinct layers: containers and quantization methods. A container defines how tensors are stored on disk. A quantization method defines how weights are squeezed into fewer bits.
- Containers: safetensors, GGUF, PyTorch pickle (.bin, .pt).
- Methods: GPTQ, AWQ, bitsandbytes NF4, llama.cpp K-quants and I-quants.
- Both at once: EXL2 and EXL3 combine a method with a storage layout tied to one inference library.
A quick memory rule of thumb
Weight memory equals parameters multiplied by bits-per-weight, divided by 8.
| Model | 16-bit | ~4.5 bits per weight |
|---|---|---|
| 8B | ~16 GB | ~4.5 GB |
| 70B | ~140 GB | ~39 GB |
This is arithmetic, not a vendor benchmark. It covers weights only. The KV cache and runtime overhead add more on top.
1. Full precision: safetensors and PyTorch .bin
Unquantized models usually ship as 16-bit weights, in either pytorch_model.bin or model.safetensors.
The older .bin and .pt files use Python pickle. Loading a pickle file can execute arbitrary code, which makes untrusted checkpoints a security risk.
Safetensors, created at Hugging Face, removes that risk. A file is a small JSON header plus raw tensor buffers, with nothing executable inside. Tensors can be memory-mapped and loaded one at a time without reading the whole file. Safetensors is now listed as a PyTorch Foundation project.
Important nuance: most GPTQ, AWQ, EXL2, EXL3, and MLX models are also stored in .safetensors files. The quantization lives in the tensor contents and a config file, not in a new container.
2. GGUF (llama.cpp)
What it is
GGUF is a binary format for running models with GGML and GGML-based executors such as llama.cpp. It was created by Georgi Gerganov, who also leads llama.cpp. It was introduced on August 21, 2023 as the replacement for the older GGML format.
Why it replaced GGML
The older GGML, GGMF, and GGJT files could not say which architecture a model belonged to. Adding a new hyperparameter broke every existing file. GGUF switched to typed key-value metadata, so new fields can be added without breaking old files.
Design goals
The spec lists 5 goals: single-file deployment, extensibility, mmap compatibility, easy loading, and complete information inside the file. Unlike tensor-only formats, GGUF can carry the tokenizer, special tokens, and a Jinja chat template alongside the weights.
Reading GGUF quant names
The suffix in a name like Q4_K_M.gguf tells you the scheme. Figures below come from the Hugging Face GGUF docs.
| Type | How it works | Bits per weight |
|---|---|---|
| Q4_0 / Q4_1 (legacy) | 4-bit round-to-nearest in 32-weight blocks; Q4_1 adds a block minimum | 4.5 / 5.0* |
| Q8_0 (legacy label) | 8-bit round-to-nearest in 32-weight blocks | 8.5* |
| Q2_K | 16 blocks × 16 weights per super-block, 4-bit scales and mins | 2.625 |
| Q3_K | 16 blocks × 16 weights, 6-bit scales | 3.4375 |
| Q4_K | 8 blocks × 32 weights, 6-bit scales and mins | 4.5 |
| Q5_K | 8 blocks × 32 weights, 6-bit scales and mins | 5.5 |
| Q6_K | 16 blocks × 16 weights, 8-bit scales | 6.5625 |
| IQ4_XS | 256-weight super-blocks, uses an importance matrix | 4.25 |
| IQ3_XXS | Same I-quant family | 3.06 |
| IQ2_XXS | Same I-quant family | 2.06 |
| IQ1_S | Same I-quant family | 1.56 |
*Derived by hand, not listed in the HF table: 32 weights plus a 16-bit scale (and a 16-bit minimum for Q4_1).
Checking the Q4_K math: A super-block holds 256 weights. 256 × 4 bits = 1,024 bits. Add 8 blocks × 12 bits of scales and minimums (96 bits). Add a 16-bit super-scale and 16-bit super-minimum (32 bits). Total: 1,152 ÷ 256 = 4.5 bits per weight.
What _S, _M, _L mean: These are mixes, not new types. For example, llama.cpp describes Q4_K_M as using Q6_K for half of the attention.wv and feed_forward.w2 tensors and Q4_K elsewhere. That is why a Q4_K_M file averages above 4.5 bits per weight.
Newer types: The HF table also lists TQ1_0 and TQ2_0 for ternary weights, plus MXFP4, a 4-bit microscaling floating-point type.
A labeling quirk: Hugging Face files Q8_0 under legacy types. In practice, Q8_0 remains the standard near-lossless GGUF choice.
Quality vs. size
Hugging Face’s reference table for a Llama-2-7B-class model shows the trade-off:
| Quant | Perplexity | Change vs FP16 | Size |
|---|---|---|---|
| FP16 | 5.9565 | baseline | 13.0 GB |
| Q8_0 | 5.9584 | +0.03% | 7.0 GB |
| Q6_K | 5.9642 | +0.13% | 5.5 GB |
| Q5_K_M | 5.9796 | +0.39% | 4.8 GB |
| Q4_K_M | 6.0565 | +1.68% | 4.1 GB |
Illustrative only. These numbers come from a 2023-era 7B model; newer models can react differently.
Importance matrix (imatrix)
GGUF quantization can use calibration data. llama.cpp’s llama-imatrix computes an importance matrix from a text file. llama-quantize –imatrix then uses it to improve quality. For 1-bit and 2-bit mixes, llama-quantize warns if no imatrix is supplied.
Naming convention
The spec defines filenames as base name, size label, fine-tune, version, encoding, type, and shard. Shards use a 5-digit counter such as 00003-of-00009. Optional mmproj- and mtp- prefixes mark vision projectors and multi-token-prediction draft modules.
Where GGUF runs
GGUF is native to llama.cpp and its ecosystem. Hugging Face documents use with llama.cpp, LM Studio, GPT4All, and Ollama.
vLLM support exists but is limited. vLLM calls it highly experimental and under-optimized, and GGUF now needs the out-of-tree vllm-gguf-plugin.
3. GPTQ
GPTQ was written by Elias Frantar (IST Austria), Saleh Ashkboos and Torsten Hoefler (ETH Zurich), and Dan Alistarh (IST Austria & Neural Magic). It first appeared on arXiv on October 31, 2022. It was published at ICLR 2023.
How it works
GPTQ is a one-shot, post-training weight quantization method. It uses approximate second-order (Hessian) information to decide how to round weights. Rounding error in one column is compensated by adjusting weights not yet quantized. It needs a small calibration dataset but no retraining.