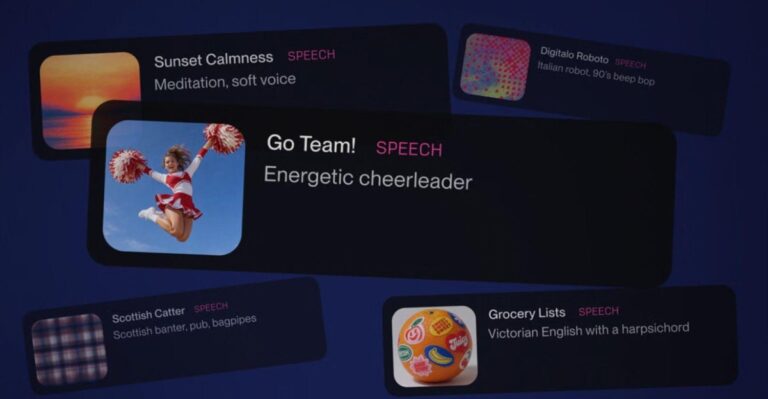
Suno has introduced a new feature called Speech that generates spoken audio paired with matching background music in a single track. Users input text and describe the desired voice and musical style, prompting the model to create the output together. Product chief Jack Brody confirmed the team tested this capability with a small group for one month before releasing it. The company suggests applications for poems, meditations, and bedtime stories, though the beta version currently contains technical flaws. Reports indicate a British accent can occasionally sound Australian due to these early bugs.
This expansion enters a legal dispute where major record labels have already sued the startup over copyright infringement. A Munich court recently rejected Suno’s fair use defence regarding the training data. The addition of speech synthesis does not resolve these legal challenges and adds another layer to the scrutiny facing AI music generators. The feature operates within the existing constraints of the company’s data usage policies.
* The beta release is still marked with known bugs affecting accent accuracy.
* No details have been provided on how the model was trained for this specific function.
* The Munich court ruling stands against the use of copyrighted data for training.