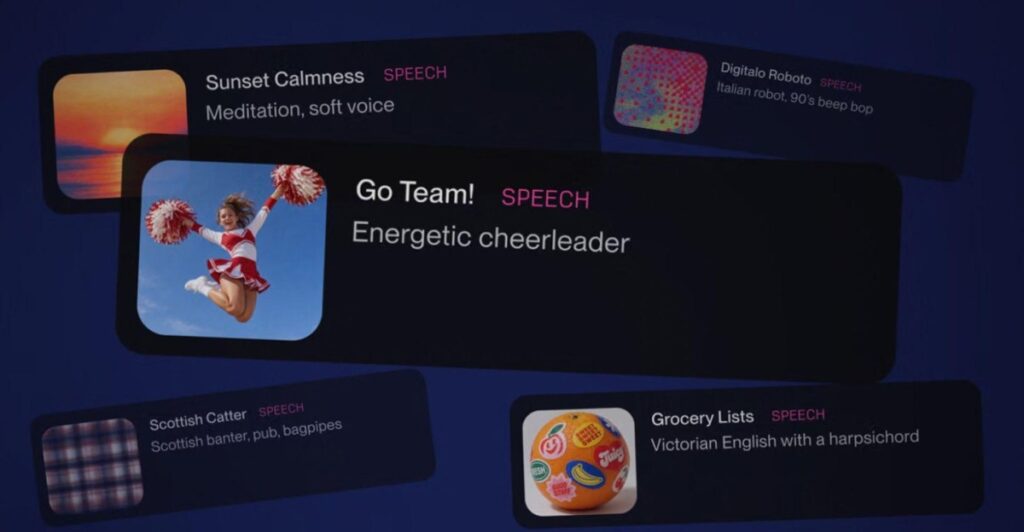
Suno has launched a public beta for its speech generation feature, allowing users to create spoken audio from text or prompts alongside background music. The tool is available on the company’s web and mobile platforms and functions as an extension of its existing music generation capabilities. Jack Brody, chief product officer at Suno, stated that while music remains central to the platform, the vision always included other forms of human expression. This update marks the first time the audio model can produce both voice and music simultaneously within a single generation workflow.
The addition matters because it consolidates two distinct production tasks into one interface, potentially reducing friction for content creators who need synchronized audio. By integrating speech directly into the music engine, Suno aims to streamline the creation of podcasts, audiobooks, or video narration without requiring separate software. The feature represents a practical expansion of the platform’s utility beyond pure musical composition.
* Available immediately in public beta
* Supports script input or descriptive prompts
* Generates voiceovers and background music simultaneously