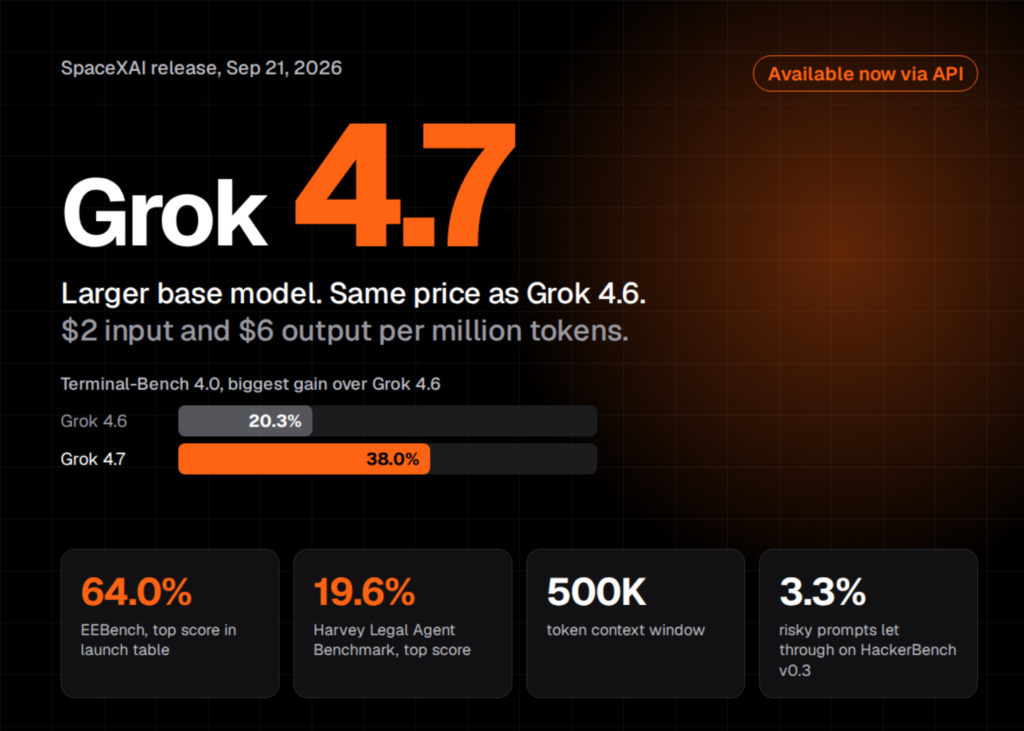
SpaceXAI has launched Grok 4.7, a larger base model designed for coding and agentic tasks, while maintaining the same $2 input and $6 output pricing as its predecessor.
The model is available immediately via the xAI API and integrated platforms including Cursor, Grok Build, OpenRouter, Vercel, and Cloudflare.
Technical updates
The company lists four primary differences between this version and Grok 4.6:
- New, larger base model: Grok 4.7 uses a different foundation than Grok 4.6.
- Extended reinforcement learning: Training focused on harder problems requiring many hours to complete.
- Improved verification: The model checks its own work more carefully and handles longer contexts better.
- Native Bot harness support: Training included specific adaptation for the Grok Bot interface.
Official documentation outlines the following specifications:
Model name: grok-4.7
Context window: 500,000 tokens
Knowledge cutoff: May 2026
Modalities: Text and image input, text output
Reasoning effort: Low, medium, high (default), xhigh
APIs: Responses API, Chat Completions
Tools: Function calling, web search, X search, code execution
Performance metrics
Comparative data places Grok 4.7 at xHigh effort against Grok 4.6 High, GPT-5.6 Sol Max, and Fable 5.1 Max. The DeepSWE score for Grok 4.7 was calculated at high effort. All figures are vendor-reported.
Benchmark results:
Input price ($/M): Grok 4.7 xHigh ($2), Grok 4.6 High ($2), GPT-5.6 Sol Max ($4), Fable 5.1 Max ($10)
Output price ($/M): Grok 4.7 xHigh ($6), Grok 4.6 High ($6), GPT-5.6 Sol Max ($20), Fable 5.1 Max ($50)
CursorBench 4.0: Grok 4.7 xHigh (46.3%), Grok 4.6 High (40.4%), GPT-5.6 Sol Max (41.7%), Fable 5.1 Max (51.8%)
DeepSWE v1.1: Grok 4.7 xHigh (71.0%*), Grok 4.6 High (65.2%), GPT-5.6 Sol Max (72.7%), Fable 5.1 Max (70.0%)
EEBench: Grok 4.7 xHigh (64.0%), Grok 4.6 High (53.0%), GPT-5.6 Sol Max (39.4%), Fable 5.1 Max (56.4%)
AA Briefcase v1.1: Grok 4.7 xHigh (1,657), Grok 4.6 High (1,546), GPT-5.6 Sol Max (1,487), Fable 5.1 Max (1,678)
Terminal-Bench 4.0: Grok 4.7 xHigh (38.0%), Grok 4.6 High (20.3%), GPT-5.6 Sol Max (37.3%), Fable 5.1 Max (57.9%)
Harvey Legal Agent Benchmark: Grok 4.7 xHigh (19.6%), Grok 4.6 High (15.8%), GPT-5.6 Sol Max (2.5%), Fable 5.1 Max (6.7%)
HealthBench Professional: Grok 4.7 xHigh (56.7%), Grok 4.6 High (48.5%), GPT-5.6 Sol Max (60.5%), Fable 5.1 Max (62.1%)
*High effort
Grok 4.7 beats Grok 4.6 in every category. The most significant improvement is on Terminal-Bench 4.0, rising from 20.3% to 38.0%. EEBench increased by 11 points to 64.0%, taking the top spot in the table. On the Harvey Legal Agent Benchmark, Grok 4.7 achieved 19.6% compared to 6.7% for Fable 5.1 Max.
Grok 4.7 does not lead across all metrics. Fable 5.1 Max wins four of the seven benchmarks, including Terminal-Bench 4.0 at 57.9%. GPT-5.6 Sol Max holds the highest DeepSWE v1.1 result at 72.7%.
Cost remains a major differentiator. Fable 5.1 Max costs five times more on input and roughly 8.3 times more on output. GPT-5.6 Sol Max is twice as expensive on input and 3.3 times more on output. SpaceXAI positions Grok 4.7 at the frontier of price-performance on a CursorBench 4.0 cost-per-task chart.
On GDPval, which measures professional knowledge work, Grok 4.7 xhigh scored 1,695 Elo. This is an increase from 1,605 for Grok 4.6 high. Fable 5.1 max leads at 1,735, while GPT-6 Astra max scored 1,542. SpaceXAI also states Grok 4.7 is superior for creating documents and presentations.
Safety and cybersecurity
Grok 4.7 includes a completely new safeguard stack. SpaceXAI describes it as the strongest model tested to date regarding refusals and jailbreak resistance. It topped LatchBio’s biosafety benchmark at 62.4%.
On HackerBench v0.3, SpaceXAI’s own benchmark for risky and malicious cyber tasks, the model allowed 3.3% of risky dual-use prompts to pass. The company notes it rarely blocks legitimate security work. Selected cybersecurity partners now have invite-only access to red-team capabilities for defense research.
Pricing and availability
Grok 4.7 costs $2 per million input tokens and $6 per million output tokens. It is available on all plans in Cursor and serves as the default model in Grok Build. Access is also provided via the Grok API, OpenRouter, Vercel, and Cloudflare.
Grok 4.7 Fast runs the same model on faster infrastructure, doubling output speed at double the price. Documentation states this version runs only in Cursor and Grok Build, excluding the public xAI API. It is also not included in Grok Build’s free tier.
A US regional endpoint at https://us.api.x.ai/v1 keeps inference within the United States at a 10% premium. SpaceXAI recommends setting a prompt_cache_key for reliable cache hits.
What it means
Developers gain a cheaper option for complex coding tasks without sacrificing speed. The lower price per token compared to competitors allows for more extensive reasoning attempts in the same budget. The improved self-verification reduces the need for manual code review in agentic workflows.