Nokia’s applied research team has released AnyJev, a Python library that converts an open large language model into a decision model without any training. The tool is designed for a specific production task: selecting one answer from a fixed list rather than generating text.
Deployment details
The library installs from PyPI and ships under the Apache-2.0 license. It supports transformers and vLLM backends using shared-prefix scoring.
What is AnyJev?
AnyJev adopts an interface similar to Jev, a decision model launched by TypeSafe AI in September 2026. You provide a typed question and receive a decision with an associated probability. This value is read from the model’s next-token distribution. No text is generated, parsed, or trained.
The library supports three question types:
- A
choicequestion selects one of K options. - A
noulquestion is a yes or no query. - A
scorequestion places the answer into one of several ordered bins.
Issues with reading logits directly
Many open projects already restrict the next token to option labels and read the scores. The Nokia research team identifies two flaws in this approach. First, the answer can change when the options are reordered. Second, the probabilities are not calibrated.
The documentation names two causes for these errors:
- Prior bias: the model favours certain labels, such as “Yes” over “No”, regardless of the input.
- Position bias: the model favours specific slots within the option list.
How AnyJev works: L0 and L1
Every decision carries a level field.
L0 (zero labels, on by default) applies two fixes:
- Cyclic shifts. For a question with K options, the list is shown in K rotations so every option appears in every position once. The results are combined in log space as a geometric mean. If the position bias is additive in logit space, this removes it exactly.
- Prior correction. By default, AnyJev uses batch calibration. It keeps a running mean of the predicted distributions on real inputs and divides it out at strength 0.75. The correction starts after 8 items.
L0 costs K prefills per decision, batched over a shared prefix. This is about 0.25 seconds per decision at batch 32 on one H100, with K = 20.
L1 (100 to 500 labels per question) adds temperature scaling on top of L0. The fitted values are saved as a small JSON artifact. L1 reshapes confidence but does not change the ranking of answers.
Benchmark results
On Qwen3-8B with BANKING77 (20-way, 300 test items), the numbers look like this:
| Metric | Raw logits | AnyJev L0 | AnyJev L1 |
|---|---|---|---|
| Labels required | 0 | 0 | 100 to 500 |
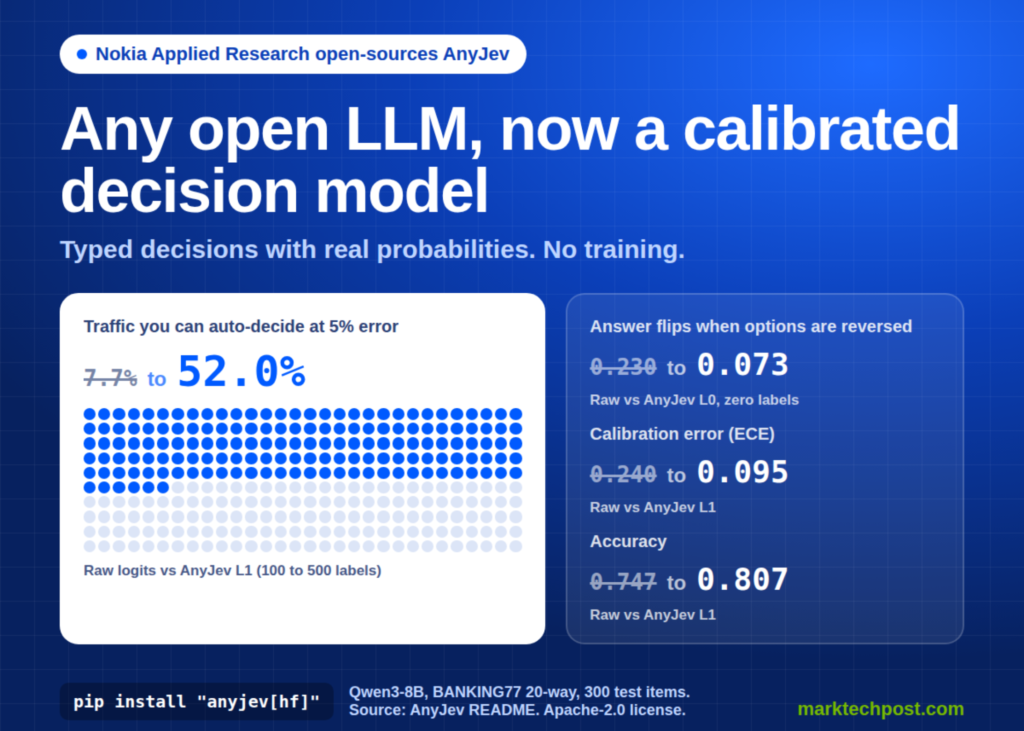
| Flip rate when options reversed | 0.230 | 0.073 | 0.077 |
| Accuracy | 0.747 | 0.803 | 0.807 |
| Calibration error (ECE) | 0.240 | 0.184 | 0.095 |
| Auto-decidable at 5% error | 7.7% | 46.3% | 52.0% |
A few other results from the repo:
- L0 reduced order flips on all 9 model and task rows tested.
- On a typed-decisions set, Qwen3-32B with L1 reached an ECE of 0.036, compared with 0.144 published for Jev. On accuracy, the fine-tuned Laya still leads.
- The full ablation table covers Qwen, OLMo, Granite, Phi and Mistral models.
- Wu says the team tried AnyJev on an internal Nokia routing problem and saw promising results.
How to use AnyJev
# pip install "anyjev[hf]"
from anyjev import Decider, Question
from anyjev.backends.hf import HFBackend

d = Decider(HFBackend("Qwen/Qwen3-8B"))
route = Question.choice("Which team should handle this?",
                        ["billing", "technical", "sales", "other"], name="route")
r = d.decide({"conversation": [...]}, [route])
r["route"].distribution   # probabilities per option
For serving, you start vLLM with prefix caching and point a VLLMBackend at it.
What it means
Developers can now take any open model and apply a layer that corrects for position and label bias without fine-tuning. This improves reliability for routing or classification tasks where the model must pick from a set of options. The L0 level provides immediate corrections, while L1 adds temperature scaling for higher precision if the workload supports the extra labels.