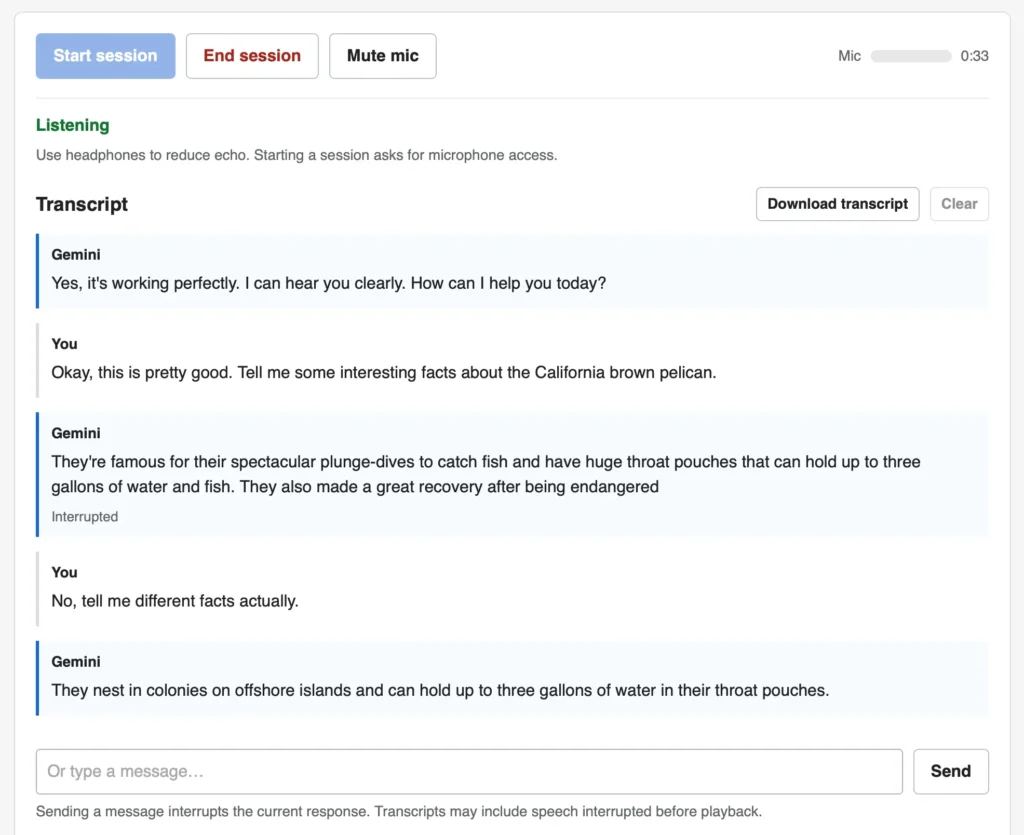
Google has released Gemini 3.8 Live and 3.8 Live Extended Thinking, two new speech-to-speech models designed to compete with OpenAI‘s GPT-Live family. A demonstration tool built by Simon Willison allows users to select a voice preset and system prompt before starting a conversation through a browser interface. The system supports user interruption while the model is speaking, with audio captured via the Web Audio API and transmitted over a WebSocket connection to the generative language endpoint. The interface displays a transcript of the exchange and includes controls to mute the microphone, adjust levels, and end the session.
This update matters because it standardises the expectation for real-time, interruptible dialogue within generative AI applications. The implementation relies on no external libraries, showing that the core functionality depends on native browser capabilities and direct API access. This approach reduces latency and simplifies deployment for developers building voice-first interfaces.
* Models include standard and extended thinking variants
* Audio handled via native Web Audio API
* Direct WebSocket connection to generative service