AI News
Drastically improve prompt processing speed for –n-cpu-moe partially offloaded models
Bigger ubatch made gpt-oss-120b prompt processing much faster on my RTX 3090 I was tuning gpt-oss-120b-F16.gguf with llama.cpp…


Bigger ubatch made gpt-oss-120b prompt processing much faster on my RTX 3090 I was tuning gpt-oss-120b-F16.gguf with llama.cpp…
Waypoint-1.5: Higher-Fidelity Interactive Worlds for Everyday GPUs Try it What is Waypoint-1.5? Waypoint-1.5 is Overworld’s next real-time video…
Meet HoloTab by HCompany. Your AI browser companion. We have developed one of the most advanced artificial intelligence…
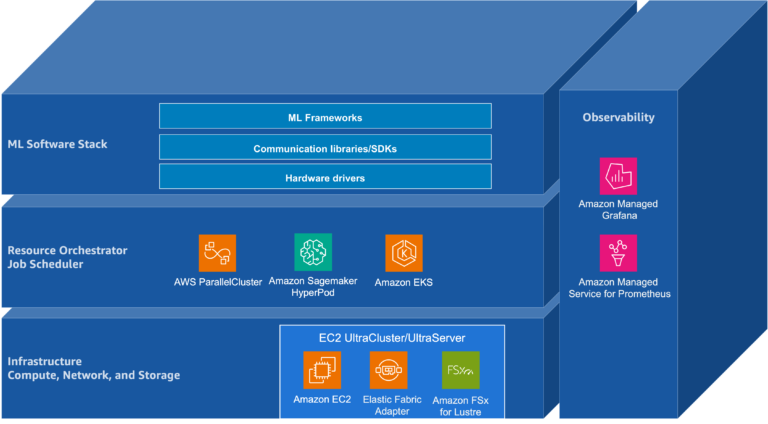
The Building Blocks for Foundation Model Training and Inference on AWS Figure: Adapted from “AI’s Three Scaling Laws,…
What’s Wrong with Our AI Overlords? I don’t have to follow every statement that Sam Altman makes about…
“`html Meta has announced Muse Spark, its first public AI model in the Muse family, following the formation…
“`html The AI company Anthropic has taken an unprecedented step by sending its Claude model for a 20-hour…
**What leaked “SteamGPT” files could mean for the PC gaming platform’s use of AI** The recent mention of…
Are Enterprises Using AI in the Wrong Places? Most enterprise AI discussions still revolve around one question: The…
Drastically improve prompt processing speed for –n-cpu-moe partially offloaded models Drastically Improve Prompt Processing Speed for –n-cpu-moe Partially…