AI News
Turboquant+MTP for ROCm(Llama CPP)
TL;DR: I got TBQ4 KV cache + MTP working on AMD ROCm for RX 7900 XTX / RDNA3…


TL;DR: I got TBQ4 KV cache + MTP working on AMD ROCm for RX 7900 XTX / RDNA3…
“`html Greetings, fellow AI enthusiasts. The thread titled “Anyone actually using a local LLM as their daily knowledge…
“`html The author of this post, a user named /u/santanah8, has started compiling real-world AI implementations from various…
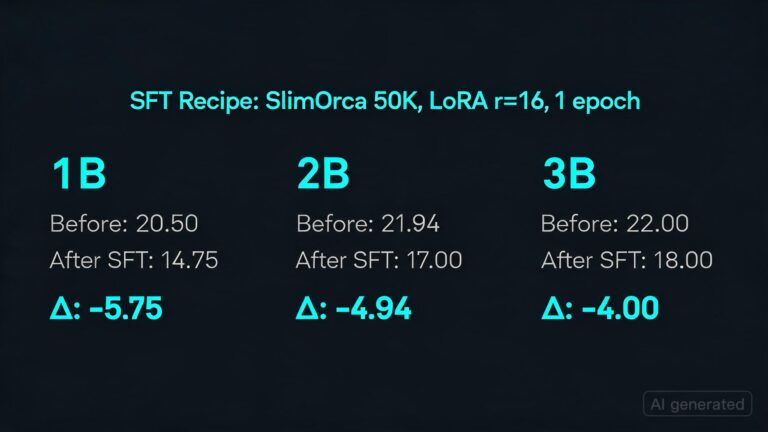
Same SFT recipe (SlimOrca 50K, LoRA r=16, 1 epoch). Three models trained from scratch at 1B, 2B, and…
A staff writer at The Atlantic, Josh Tyrangiel, recently appeared on “The Daily Show” to discuss his book…
“`html The post observes a significant shift in punctuation usage, particularly the increase in em-dashes, in AI-generated text…
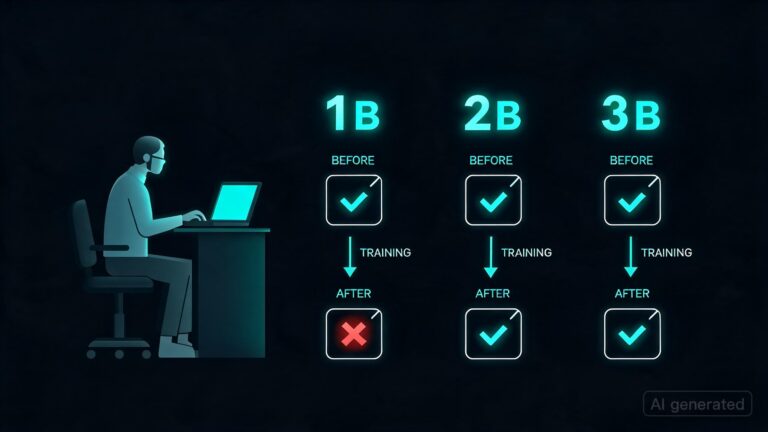
**What Happened:** A Reddit user, GPUburnout, conducted an experiment where they trained three language models (1B, 2B, and…
“`html A British AI startup called Vitalops has released a tool named opendesk, which allows an AI agent…
“`html Token Superposition Training Overview The Problem TST Is Solving Modern LLM pre-training is heavily data-driven. Recent training…
Who decides what AI tells you? Campbell Brown, once Meta’s news chief, has thoughts Campbell Brown, who spent…