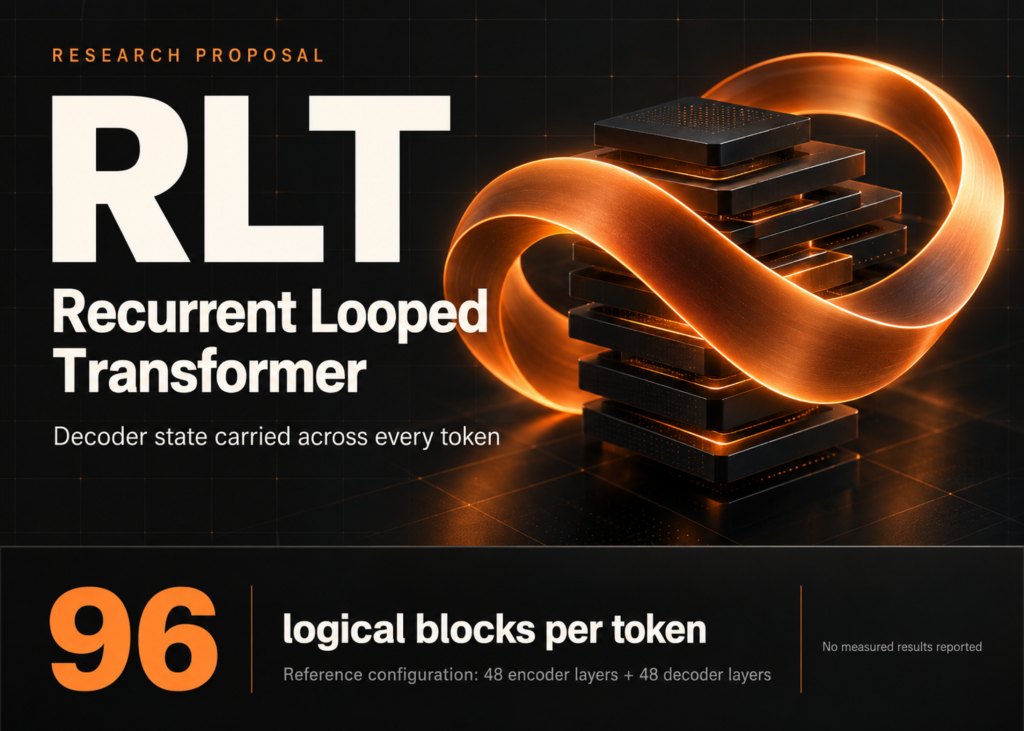
A technical report from Yifan Zhang at Princeton proposes a Recurrent Looped Transformer (RLT) architecture that carries the decoder’s final hidden state and its layerwise sliding-window attention cache into every subsequent token, eliminating the standard reset at prompt-response boundaries.
The Architecture
The system pairs a causal encoder with a recurrent decoder. The encoder processes tokens in parallel under a causal mask to produce representations, which are then projected into key-value memory. This memory can be shared across all decoder layers or kept specific to each layer.
The decoder maintains the recurrence loop. Its complete state combines the final output with retained keys and values for every layer. For each new token, a gated merge combines the encoder representation with the previous output. Each decoder block then runs causal sliding-window attention over decoder activations, cross-attention to encoder memory, and a feed-forward network. The attention window includes the current token, retaining at most one fewer historical entry per layer than the window size. The model reads the next-token distribution from the current output, initializing once before the beginning-of-sequence token with a learned start state and an empty cache.
The reference configuration uses 48 encoder and 48 decoder layers with compatible attention and feed-forward weights shared between them. Each token executes 96 logical blocks, though decoder blocks add cross-attention so per-block floating-point operations are not equal. Zhang describes this as parameter reuse rather than activation copying.
Design Principles
Latent reasoning with unbounded temporal depth: After processing t tokens, the state path traverses t multiplied by the number of decoder layers. In the reference configuration, this equals 48t. Per-token work remains fixed while the structural depth grows with the sequence. The report warns that gates and contraction may suppress long paths, so structural depth is not a guarantee of reasoning performance.
Model-hardware co-design: Encoder features and memory projections for known tokens use token-parallel kernels. Decoder transitions remain sequential within a sequence, but ready updates from independent sequences can share one batched kernel. The report states plainly that no exact parallel scan is assumed for the nonlinear decoder, no reduced-prefill speedup is claimed, and a standard parallel sliding-window attention decoder pass is not equivalent to the recurrence. Batching, kernel fusion, and checkpointing are listed as implementation targets, not completed kernels.
Model-RL algorithm co-design: Pretraining, supervised fine-tuning, sampling, and reinforcement learning replay share one state transition. For reinforcement learning, the sampler records each action’s behavior log-probability under its actual sampling distribution, including temperature and truncation. The trainer rebuilds encoder memory, the recurrent output, and every sliding-window attention cache from the sequence start under current parameters before scoring each action; old rollout states are never reused. Proposition 3.1 formalizes the payoff: moving the prompt-response split leaves the conditional distribution unchanged for a fixed token history.
Training and Serving
Pretraining uses full-sequence next-token prediction with full backpropagation through time. Supervised fine-tuning masks the loss to assistant targets but never masks state updates, so assistant losses backpropagate through user and tool tokens. Appendix B shows why partial detaching is risky: the state-to-state Jacobian has cross terms through decoder key-value pairs, so detaching only the output leaves gradient paths through the cache; any truncated-backpropagation-through-time scheme must name every detached tensor.
For multi-turn serving, an exact prefix snapshot includes the encoder cache and memory, the complete decoder state, position metadata, the window convention, and model version. A fixed-weight snapshot can be reused because the state is independent of the serving split; weight updates invalidate old states, and editing a prefix forces recomputation from an earlier checkpoint. External tokens in multi-turn reinforcement learning update the state but receive no importance-ratio factors.
Prior Work
Encoder-derived memory follows YOCO, which caches key-value pairs once for a cross-decoder, and DeepSeek-V4.1-Flash, which projects decoder global key-value pairs from final encoder states; RLT keeps the memory but drops prompt-wide decoder skipping. Temporal feedback builds on the Feedback Transformer and Recurrent Transformer; RLT instead feeds the previous final decoder output into the next decoder input and runs recurrence over the prompt too. Depth-wise reuse connects to Universal Transformers and recurrent-depth latent reasoning; the replay argument extends Zhang’s prefill-decode kernel mismatch note.
What it means
Developers building on this architecture must accept that the model does not reset its internal state between user input and model response. This creates a continuous computational path that grows with every token generated. While this offers a specific route for latent reasoning, the report explicitly notes that no measured efficiency or reasoning quality results are available yet.