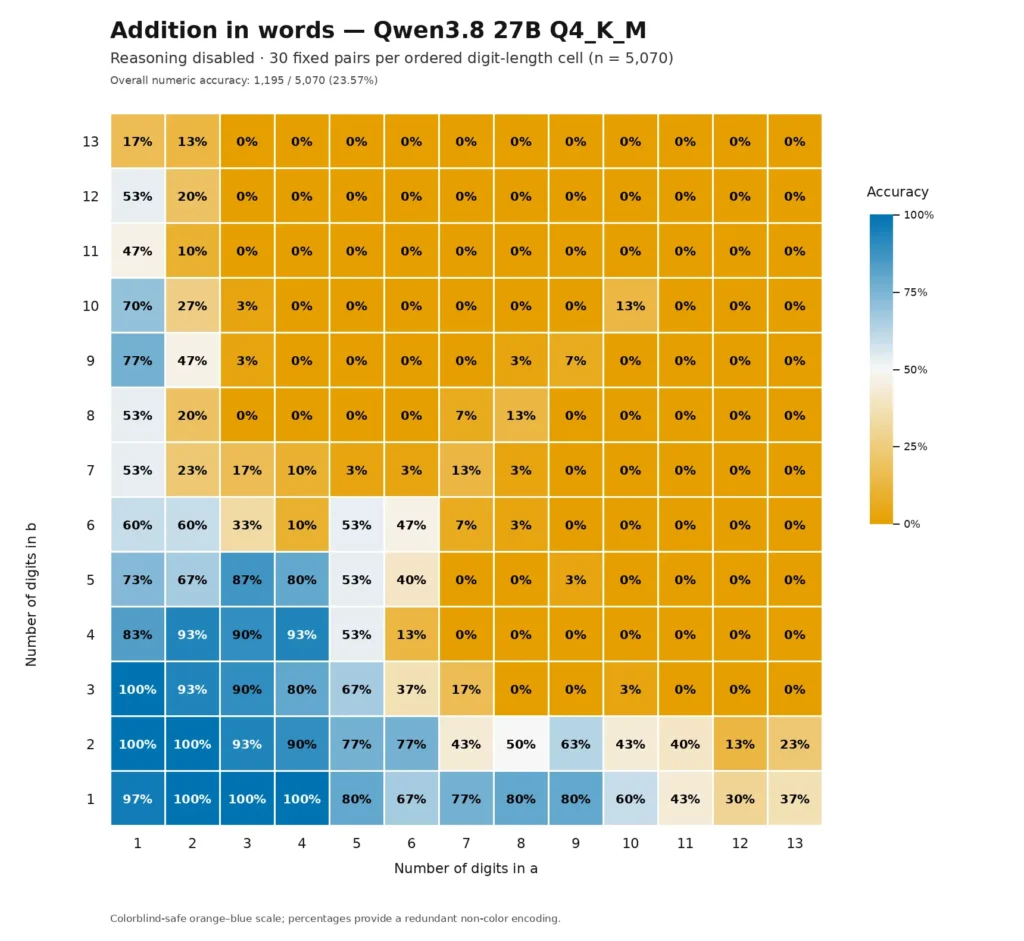
Colin Frasier posted a chart on Bluesky showing how GPT-4o failed to compute sums in words when the numbers grew large. Simon Willison repeated this test on a DGX Spark using Qwen3.8-27B with reasoning disabled. The new model performed worse than the earlier GPT-4o results, achieving only 23.57% accuracy across 5,070 attempts. The heatmap shows accuracy dropping sharply as digits increase, with near-zero success for numbers exceeding ten digits. This demonstrates that current open models struggle with basic arithmetic when forced to output natural language instead of digits.
The failure highlights a specific limitation in how these models process numerical data internally. They appear to rely on pattern matching rather than actual calculation for large values. This matters for applications requiring precise financial or scientific reporting where hallucinations are unacceptable. Developers must account for this weakness when designing workflows that depend on verbalised math.
- Overall numeric accuracy was 1,195 out of 5,070 attempts.
- Success rates fell to 0% for any combination involving thirteen digits.
- The test used a Q4_K_M quantised version of the 27 billion parameter model.