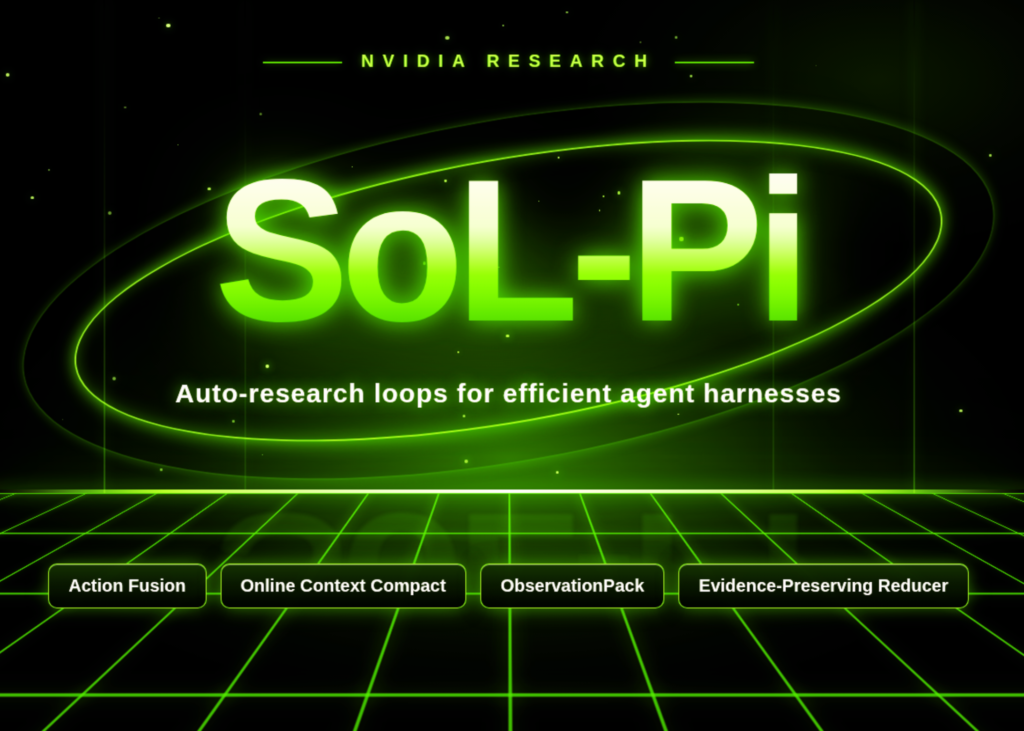
A new coding agent extension called SoL-Pi reduces the number of tokens coding agents consume by up to 49%. Researchers from NVIDIA, NTU and MIT released the tool on September 21, 2026. It is an open-source add-on for the Pi coding agent.
The system cuts recorded token traffic by 44.7% to 49.0% on the EdgeBench test suite. API costs drop by roughly 33%. Performance scores remain close to the original Pi model on both GPT-5.6 Sol and Opus 5 backends.
Deployability and licensing
SoL-Pi is available on GitHub under the NVlabs account. It is released under an MIT licence. Developers can install it as an extension on an unmodified Pi release. Testing confirmed compatibility with Pi version 0.85.1 and Node.js 22.19 or newer.
Why focus on the harness layer
Most efficiency research lowers cost per token through faster kernels or cheaper models. SoL-Pi instead reduces the total volume of tokens a task consumes. The harness is the software layer that manages tool calls, context, observations and delegation.
Manual tuning of a harness is slow. Changes in one area often push costs into later steps. Existing systems like Meta-Harness automate this work. However, a recent study found that evolved harnesses can overfit to specific search tasks. They deliver only marginal gains on unseen tasks.
The search methodology
A research AI observes execution traces from a separate agent running the base Pi model. It then proposes harness changes and tests them. The search covered 152 proposed directions across six families: context, progress, tools, delegation, prompt and policy, and improvement and evaluation.
The team tested 535 executable environments. These included 495 built from GitHub issue-pull request pairs and 40 synthetic tasks with executable verifiers. The process involved more than 3,000 runs and over 60,000 agent-environment interactions.
Each search operates as a disposable, isolated loop. It follows the autoresearch cycle, extended with a Ralph Loop implementation step and an independent reviewer. Acceptance rules are fixed before the search begins. The optimizer cannot change them. Every capability metric must stay within a predeclared tolerance. The candidate must also improve at least one efficiency metric.
EdgeBench remains held out. Of its 51 public tasks, 11 are used for one-way acceptance of frozen candidates and 40 for final evaluation. Held-out results never feed back into the search.
The four surviving mechanisms
Four mechanisms survived the search process. They are:
- Action Fusion: Base Pi often edits a file and then issues a separate command to test, build or run it. Action Fusion merges both into one tool request and returns both outcomes in one observation. This removes a model round trip.
- Online Context Compact: Plan steps are tracked through the
update_planfunction. When a step completes, the harness estimates how many requests remain. It then compares the projected input savings with the extra cost of rewriting the prompt cache. It invokes Pi’s native compaction when this gate passes or when context nears the window limit. - ObservationPack: Tool outputs above 10 KiB are archived locally and sent in full for the next two provider requests. From the third request onward, the model sees a stable handle, the original size and a short excerpt of head and tail lines. Exact pages stay retrievable through the handle.
- Evidence-Preserving Reducer: Build and test logs of at least 4 KiB go to a cheaper model, GPT-5.6 Luna at
high, which writes a compact receipt. A deterministic verifier checks the receipt’s schema, source hash, exit status, exact quotes and size. The harness falls back to the original log in three cases: verification fails, credentials are suspected, or the receipt is not smaller.
Results on EdgeBench
The full stack was built on GPT-5.6 Sol and moved to Opus 5 without further search. On Opus 5, it keeps 94.3% of Pi’s score while cutting token traffic by 44.7% and API cost by 33.5%. On GPT-5.6 Sol, it keeps 93.7% of Pi’s score with 49.0% fewer tokens and 33.2% lower cost.
The Performance point uses the best single mechanism for each backend: ObservationPack on GPT-5.6 Sol and Action Fusion on Opus 5. It lifts scores 5.3% and 12.8% above Pi.
On GPT-5.6 Sol, the full stack increases cache-write traffic from 0.0141 B to 0.0316 B tokens. Total cost still falls, from $1,339 to $894. The paper estimates hourly savings of $8.75 to $13.50 versus the native Codex and Claude Code harnesses, and $4.36 to $5.71 versus Pi.
Performance on other benchmarks
Testing on Terminal-Bench 4 (63 CPU-only tasks) showed SoL-Pi solves 15 tasks versus 18 for both Codex and Pi. It lowers total cost by 26.3% versus Pi ($211.12 vs $286.45).
On IMO 2026, Lean 4-verified problems, SoL-Pi passes 3 of 6 problems, matching Pi, at the lowest cost per passed problem ($20.90). Codex passes 5 problems.
In an agent swarm test, a Codex coordinator with 20 SoL-Pi workers reached 1,127 cycles at $60.11. With 20 Pi workers, it reached 1,366 cycles at $82.12. A single Codex agent was still the cheapest option at $39.20 and reached 1,333 cycles.
The research team calls the cross-model transfer preliminary. The mechanisms trigger less often on Opus 5, possibly because the search used only GPT-5.6 Sol trajectories.
What it means for developers
Developers using Pi or similar coding agents can install SoL-Pi as an opt-in extension. The change reduces the volume of data sent to the model. This lowers bills for large-scale projects without sacrificing the ability to complete tasks. The four mechanisms handle file edits, context management and log reduction automatically. No manual configuration is required.