
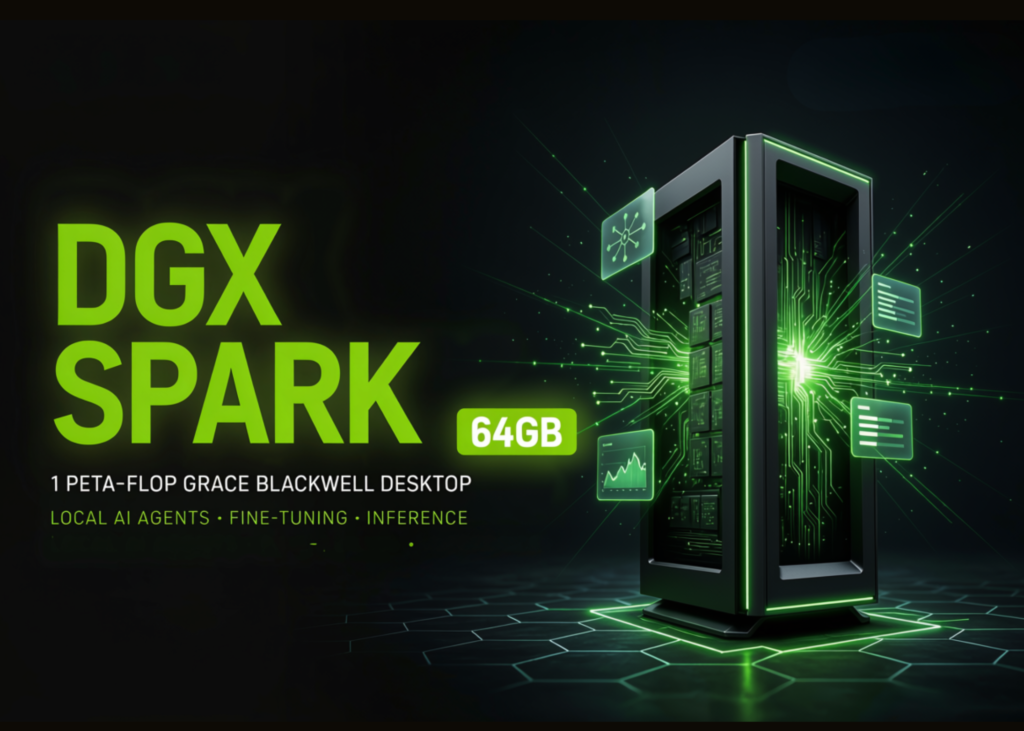
NVIDIA has launched a 64GB version of the DGX Spark desktop, a Grace Blackwell system built by Acer, ASUS, Dell, Gigabyte, HP, and MSI. This unit offers developers a single machine to run local models and agents, with the option to cluster two 64GB systems to reach 128GB of memory and higher compute power as needs expand.
The core message is clear: run open models and always-on agents on your own desk, then cluster the DGX Spark as workloads grow, rather than relying on metered cloud APIs.
The timing is specific. Agents consume tokens continuously through tool calls, retries, and long context windows. Token usage has risen 14-fold since early 2026. On a cloud API, every token costs money. On owned hardware, there is no per-token fee.
The 64GB model retains the GB10 Grace Blackwell superchip, the NVIDIA CUDA accelerated software stack, and ConnectX-7 networking found in the original design, updated with 64GB of unified LPDDR5x memory instead of 128GB. NVIDIA states this capacity is sufficient for today’s most capable 30–35B class open models. The 128GB DGX Spark remains available for larger single-box workloads, while clustering 64GB units adds memory and compute together.
What is Inside the Box
The GB10 superchip pairs a Blackwell GPU with 5th-generation Tensor Cores and a 20-core Grace Arm CPU. The GPU delivers up to 1 petaFLOP of FP4 AI compute, utilizing sparsity.
| Spec | DGX Spark 64GB |
| Superchip | NVIDIA GB10 Grace Blackwell |
| CPU | 20-core Arm (10× Cortex-X925 + 10× Cortex-A725) |
| AI compute | Up to 1 petaFLOP FP4 (with sparsity) |
| Memory | 64GB LPDDR5x, coherent unified |
| Memory bandwidth | 273 GB/s |
| Storage | 1, 2, or 4TB NVMe M.2, self-encrypting |
| Networking | ConnectX-7 NIC, 200GbE; Wi-Fi 7, BT 5.3 |
| Display | 1× HDMI 2.1a |
| OS | NVIDIA DGX OS (Ubuntu-based) |
| Size / weight | 150 × 150 × 50.5 mm / 1.2 kg |
| Max local model size | Up to 100B parameters |
| Availability | Oct 23, 2026 — NVIDIA Marketplace, OEM partners, retail |
Source: NVIDIA specifications.
Unified memory is the key design choice: The CPU and GPU share one memory pool over NVLink-C2C, operating at five times the bandwidth of PCIe Gen 5. There is no need to copy weights between system RAM and VRAM. For agents, this means several models, their KV caches, and tool processes live in a single address space.
The software is ready on first boot: DGX OS ships with the NVIDIA AI stack, including PyTorch, Jupyter, and Ollama. NVIDIA NemoClaw installs with a single command. It adds privacy and security controls to OpenClaw agents. NVIDIA OpenShell, part of the NVIDIA Agent Toolkit, adds policy-based guardrails. NVIDIA Nemotron models are optimized for the box.
It runs on a standard wall outlet: No server room or special cooling is required. This matters for an agent meant to run around the clock.
Built-in networking for clustering: ConnectX-7 allows two DGX Spark 64GB systems to cluster for 128GB of memory and increased compute. NVIDIA Sync Cluster Assistant simplifies the setup.
Which Open Models Fit in 64GB
Hardware is half the story. The other half is that 30B-class open models have become capable enough for agent work.
| Model | Developer | Type | Footprint | Role on a Spark |
| Muse Glimmer | Meta | 29.6B dense, text + image, Apache 2.0 | ~17GB (quantized) | Main agent model |
| Nemotron 3.5 Lightning | NVIDIA | 30B MoE (30B-A3B) | NVFP4 checkpoint | Fast executor for long-running agents |
| Qwen3.8-27B | Alibaba Qwen | 27B dense | ~13.5GB weights (4-bit) | General agent and coding |
Footprints are weight-only estimates; KV cache and runtime overhead come on top.
Muse Glimmer is the main model. Meta distilled it from Muse Spark, the model family behind the Meta AI assistant. It targets local agents: reliable tool calls, long multi-step tasks, and recovery from failures. Meta reports a score of 51.2 on SWE-Bench Pro and 75.5 on MCP Atlas. Context runs to 131K tokens. It is also available as an NVIDIA NIM.
Full BF16 Glimmer needs 55GB or more, which leaves almost nothing for context. The ~17GB quantized build is the practical choice on 64GB.
Larger models like DeepSeek V4 Flash require more than one box. NVIDIA’s own benchmarks run it on four 64GB clustered Sparks.
5 Things You Can Build on One Box
1. An always-on personal agent
Install Hermes and point it at Muse Glimmer or Nemotron 3.5 Lightning. Give it tools: your GitHub repos, a test runner, an RSS feed of arXiv categories. Let it run overnight.
By morning it has triaged new issues, reproduced a failing test, and drafted a pull request for review. It has also summarized the 30 papers you would never have opened. Your private notes, code, and email never leave the machine.
2. Fine-tune a coding model on your own repo
QLoRA on a 70B model fits in 64GB. Train it on your codebase, internal docs, and past PR reviews. Then serve it locally as a coding assistant that knows your conventions.
NVIDIA measured approximately 18,400 tokens per second on a single node for nanochat distributed fine-tuning.
3. A day-1 model evaluation bench
A new open-weight model drops on Hugging Face. Pull it through Ollama or vLLM the same day. Run your own question set against it.
Score accuracy, then measure time to first token and tokens per second. Compare it against your current model. There is no API bill for re-running the evaluation 50 times.
4. A multi-model agent team
Unified memory lets several models share one pool. Run Bonsai 2 as a router, and Glimmer as the main reasoning agent. That is roughly 23GB of weights.
The rest covers KV cache, the OS, and tool processes. When a problem exceeds local capacity, the agent can send a sanitized question to a larger cloud model.
5. Edge and robotics prototyping
Fine-tune a vision transformer for a specific task, like spotting anomalies on a factory floor camera. Validate it locally with the same CUDA stack. Then deploy it to an NVIDIA Jetson device at the edge.
When One Box is Not Enough: Clustering with NVIDIA Sync
Every DGX Spark ships with ConnectX-7 at 200GbE. Clustering is a native feature, not an add-on.
| Setup | Pooled memory | AI compute (FP4) | Connection |
| 1 Spark (64GB) | 64GB | Up to 1 PFLOP | — |
| 2 Sparks (64GB each) | 128GB | Up to 2 PFLOPS | Direct QSFP cable, no switch |
| 2 Sparks (128GB each) | 256GB | Up to 2 PFLOPS | Direct QSFP cable, no switch |
| 3 Sparks (128GB each) | 384GB | Up to 3 PFLOPS | QSFP ring, no switch |
| 4 Sparks (128GB each) | 512GB | Up to 4 PFLOPS Source Read original → Related articles   |