NeoMME: an efficient Multimodal-native and Multilingual Encoder
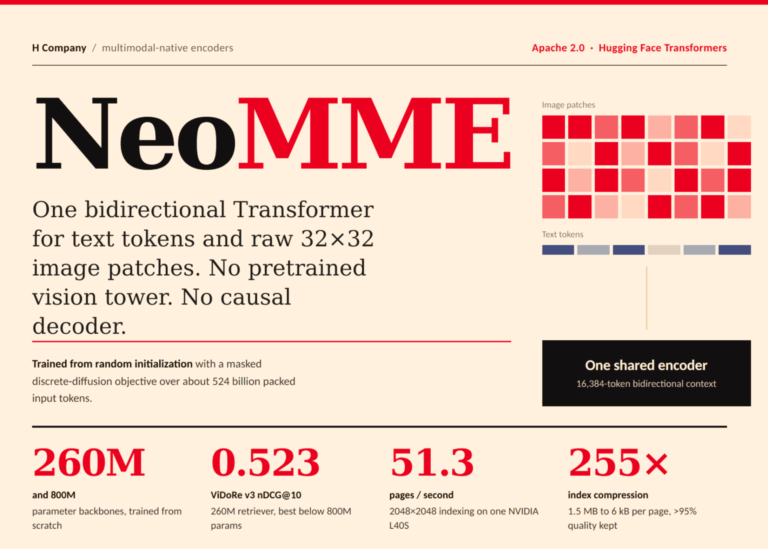
NeoMME is a family of 260M and 800M parameter encoders that process text and images within a single bidirectional Transformer, trained entirely from scratch using a masked discrete-diffusion objective.
Why another multimodal encoder?
Most recent visual document retrievers rely on pretrained generative models. These systems separate the vision encoder from the language model, requiring a projector to map visual features into the text space before a causal decoder handles the combined input. Retrieval tasks do not generate text autoregressively, so they do not require this overhead.
ModernBERT improved bidirectional encoders, but ModernVBERT retained a separate pretrained SigLIP2 vision tower. The researchers wanted to eliminate the parameter and compute costs associated with carrying over a VLM architecture.
NeoMME generates vector representations for input text and images using one Transformer encoder. It does not depend on an existing pretrained vision tower, text encoder, or text decoder. This unified path allows for easier pretraining, fine-tuning, parallelization, and serving across both modalities.
NeoMME encoder backbone
One Transformer for images and text
The two variants share the same architecture:
- Native multimodal inputs: text inputs use factorized token embeddings, while images are divided into a grid of non-overlapping 32×32 patches and projected with a small MLP. Both enter the same Transformer encoder.
- Dynamic image resolution: images keep their aspect ratio and size. This allows the model to use more tokens on a high-resolution, information-dense document page than on a smaller image with less content.
- Long bidirectional context: both models have a context length of 16,384 tokens, enough for up to two standard 3840×2160 4K UHD images. Most layers use symmetric sliding-window attention, while every sixth layer and the final layer use global attention.
- A modern encoder stack: NeoMME uses recent encoder improvements such as grouped-query attention, query-key normalization, gated attention, 2D rotary position embeddings, and squared-ReLU MLPs, among others.
- Multilingual text: the team trained a BPE tokenizer with a 131k-token vocabulary from scratch on multilingual text, code, mathematics, and machine-produced image transcripts.
Learning from images through masked text
The team pretrained NeoMME from scratch as a discrete masked-diffusion text denoiser. For each text-only example, they sampled a corruption rate uniformly between 0 and 1. Each eligible text token was then independently masked at that rate.
Multimodal examples used corruption rates between 0.3 and 1. The image patches remained visible while NeoMME reconstructed masked text. With light masking, the model could often recover a missing word from the surrounding text alone. For example, “cat” is a plausible completion of “The [MASK] sat on the mat,” even without an image. But high masking forced the model to learn image-grounded descriptions with little to no signal from the non-masked input text tokens.
Pretraining mixed multilingual text, code, mathematics, natural images, and document images. Each model processed about 524 billion packed input tokens, including 290 billion tokens from text-only examples. This text budget was relatively small compared with ModernBERT’s 2 trillion training token budget. Hence, the team chose the NorMuon optimizer to improve data efficiency during training.
NeoMME-Retriever
To get a meaningful downstream evaluation of the backbone, the team fine-tuned NeoMME for visual document retrieval using the page-image methodology introduced by ColPali. While traditional text-based retrieval consists of retrieving text chunks, NeoMME-Retriever ranks document page screenshots and bypasses all the preprocessing OCR steps necessary to extract text from PDFs. Treating the pages as images preserves layout, charts, tables, font type and size, and other visual clues that cannot be captured even by a perfect OCR model.
A dual-head design for dense and late-interaction retrieval
NeoMME-Retriever reuses the NeoMME backbone but adds two jointly trained heads on top of it for retrieval:
- The dense head averages the backbone’s hidden state vectors into a normalized vector (mean pooling). Dense embeddings are most common today: they are compact and work naturally with approximate nearest-neighbor (ANN) techniques for fast retrieval.
- The late-interaction head projects each text token or image patch from the backbone’s output hidden states to a 128-dimensional normalized vector. Compared to dense embeddings, the finer granularity preserves local matches between individual query tokens and image regions.
Omar Khattab, who introduced late-interaction in ColBERT, explains why the term is more precise than “multi-vector.” It describes the granularity and learnability of the scoring function, not simply the number of stored vectors.
To learn more about late-interaction, we recommend reading this crash course by Amélie Chatelain.
One NeoMME-Retriever forward pass returns both representations, which gives users flexibility no matter their use case and infrastructure. The team recommends using late-interaction embeddings in general since they are more powerful and can be used easily with open-source libraries like NextPlaid. However, if a user has a very large corpus, they can run a single forward pass with NeoMME-Retriever to get the dense embedding, retrieve a small number of documents through an ANN index, and then use late-interaction to rerank the retrieved candidates.
Competitive retrieval at compact model sizes
The team reported nDCG@10 on ViDoRe v3. NeoMME-Retriever-260M reached 0.523, the highest score among evaluated models strictly below 800M parameters. It was within 0.002 nDCG@10 of ColQwen2.5 while using about 14× fewer parameters. NeoMME-Retriever-800M reached 0.556, within 0.009 nDCG@10 of the similarly sized Vultron Retriever Flash (0.8B). Both NeoMME-Retriever models lie on the model-size Pareto frontier.
ViDoRe v1 and v2 use nDCG@5. On both benchmarks, NeoMME-Retriever-260M outperformed ColModernVBERT and the twice-larger ColSmol-500M. NeoMME-Retriever-800M outperformed ColPali v1.3 while using 3.6 times fewer parameters.
| Model details | ViDoRe (nDCG@k) | |||
|---|---|---|---|---|
| Model | Params. | v3 (@10) | v2 (@5) | v1 (@5) |
| <300M | ||||
| ColModernVBERT | 250M | 0.261† | 0.407‡ | 0.806‡ |
| ColSmol-256M† | 256M | 0.207 | 0.348 | 0.797 |
| NeoMME-260M‡ | 260M | 0.523 | 0.522 | 0.860 |
| 300M to 1B | ||||
| ColSmol-500M | 500M | 0.340‡ | 0.455† | 0.825† |
| Vultron Flash† | 850M | 0.565 | 0.604 | 0.882 |
| NeoMME-800M‡ | 800M | 0.556 | 0.559 | 0.874 |
| >1B | ||||
| ColQwen2.5-v0.2† | 3.75B | 0.524 | 0.601 | 0.895 |
| ColPali v1.3† | 2.92B | 0.430 | 0.547 | 0.848 |
† Scores from MTEB. ‡ Results from the team’s own evaluations.
Making high-resolution retrieval practical for late-interaction
Late-interaction storage scales linearly with the number of vectors in the output embedding. Higher-resolution images contain more patches, so they produce larger embeddings. For example, a 2048×2048 square page produces embeddings containing 4,200 vectors with NeoMME-Retriever, or about 2.1 MB in float32. Across the ViDoRe v3 benchmark, the measured average is about 1.5 MB per document.
To reduce the storage footprint of the late-interaction index, the team combined two complementary compression methods:
- Hierarchical token pooling clusters similar document vectors in a given multi-vector embedding and replaces each cluster with its mean, hence reducing the number of vectors stored for each page.
- Asymmetric quantization quantizes document embeddings to int8 or binary. Because query embeddings are not stored and only generated on-the-fly, they can be kept at a higher precision.
The team tested this setup on ViDoRe v3. With a pooling factor 10 and int8 queries and documents, storage decreased from about 1.5 MB to 39 kB per page, a 39× reduction, while keeping more than 99% of the baseline nDCG@10. A more aggressive configuration used pooling factor 8, int8 queries, and binary documents. That version used 6 kB per page (255× smaller) and kept more than 95% of the original retrieval quality.