AI News
Drastically improve prompt processing speed for –n-cpu-moe partially offloaded models
“`html A British Reddit user shared a technique for significantly improving the processing speed of large language models…


“`html A British Reddit user shared a technique for significantly improving the processing speed of large language models…
“`html I built Derpy Turtle: The Kokoro Trainer, a GUI for training better Kokoro voices with RVC Derpy…
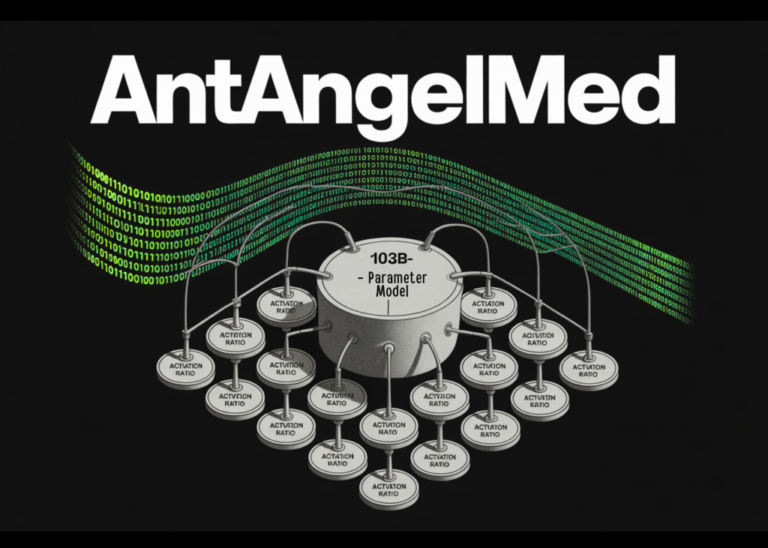
“`html Meet AntAngelMed: A 103B-Parameter Open-Source Medical Language Model Meet AntAngelMed: A 103B-Parameter Open-Source Medical Language Model MarkTechPost…
Father and daughter making breakfast together – using ChatGPT and Higgsfield AI A father and his young daughter…
“`html A Reddit user is seeking advice on how to boost their AI model’s throughput (TPS) and context…
“`html A Reddit user shared a method to significantly boost the processing speed of prompts for large language…
**What Happened:** A user on the r/LocalLLaMA subreddit asked a question about whether using vLLM (an open-source variant…
**Editorial Brief** The article highlights a concerning trend where AI companies, which have previously undermined public trust through…
**Editorial Brief** The question of whether to upgrade from an RTX 5060Ti with 16GB VRAM to either a…
Drastically improve prompt processing speed for –n-cpu-moe partially offloaded models I was tuning gpt-oss-120b-F16.gguf with llama.cpp on a…