TRL v1.14 now supports training LoRA adapters with AsyncGRPOTrainer and syncing only those adapters to vLLM. This allows the training process and inference workers to run on separate Hugging Face Jobs without needing NCCL or a shared machine.
The core change
LoRA training fits reinforcement learning well because the advantage function provides limited information per episode. A rank-1 adapter has enough capacity to absorb this data. A rank-1 adapter for a 1.5B model is a few megabytes, whereas the full model is around 3 GB. Instead of moving gigabytes after every update, the system sends just the adapter. vLLM can keep several adapters loaded simultaneously. Older rollouts finish using the policy they started with, while new rollouts use the latest version.
Separating the jobs
TRL’s AsyncGRPOTrainer separates training and generation. Previously, the trainer and vLLM could run on different machines if they shared a filesystem or formed an NCCL group. Hugging Face Jobs run one container per VM and cannot spawn multiple nodes to host a trainer and a fleet of vLLM servers. The setup is limited to eight H200 GPUs per node. The question became how far the system could go if the trainer and inference servers did not share a node.
Syncing full weights across machines requires gigabytes of data transfer, which NCCL handles in dense clusters. Hugging Face Jobs cannot communicate across nodes in that way. There is no shared local disk and no localhost connection. With LoRA, the sync is only a few megabytes. Hugging Face Jobs provide volumes backed by Storage Buckets. These buckets mount as a FUSE filesystem in every Job and act as a shared filesystem between nodes. No network path between the Jobs is needed.
Architecture and storage
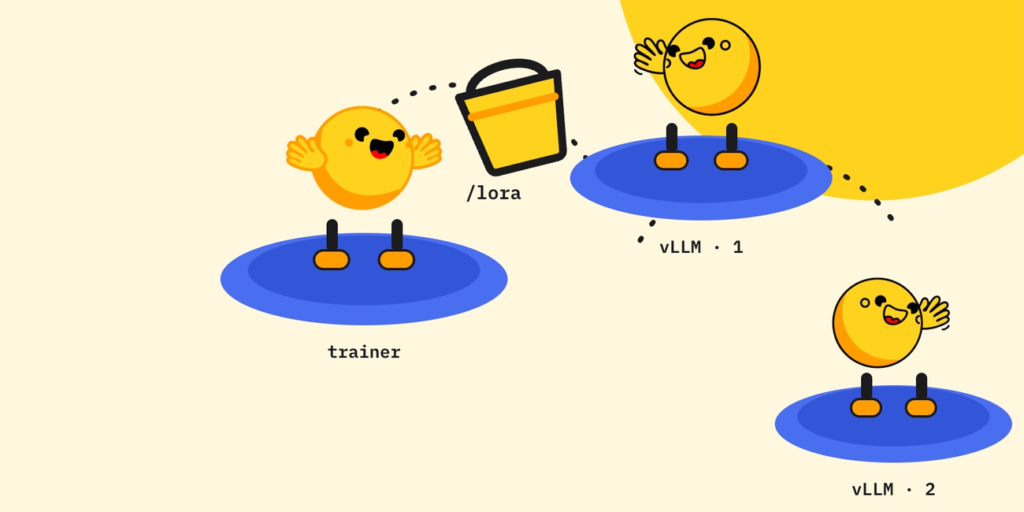
The adapter-only sync path works as follows. The trainer saves the adapter under a specific output directory and publishes the directory with an atomic rename. It then sends the path to vLLM’s /v1/load_lora_adapter endpoint. vLLM loads the files from disk, allowing the rollout worker to request the new model version.
Runtime adapter loading in vLLM takes a path, not tensors. The trainer and server must share a filesystem. On a Slurm cluster, that is the network filesystem. On Jobs, the system mounts a Storage Bucket as a volume at the same path in every Job. This uses hf-mount to expose the bucket as a POSIX filesystem inside the container.
The system stores checkpoints and the final adapter in the bucket. Hugging Face Jobs are ephemeral, but a preempted trainer can resume training because the final adapter persists to the bucket and is never lost when the Job stops.
Job configuration
The setup consists of three parts. A trainer Job runs AsyncGRPOTrainer with LoRA and FSDP. Two vLLM Jobs serve the base model plus whatever adapter the trainer last published. A Storage Bucket mounts in all three jobs at the same path to move the adapter from trainer to servers. A proxy server routes each rollout to the replica holding its KV cache and broadcasts adapter updates to all vLLM replicas.
vLLM replicas
Each replica uses one GPU and the stock vllm/vllm-openai image. The system enables runtime LoRA loading and reserves enough adapter slots.
The number of adapter slots follows from max_staleness. In AsyncGRPOTrainer, every weight sync bumps the policy version by one. Max_staleness is how many versions a rollout sample may lag behind the current policy before the trainer discards it. With max_staleness=4, a sample generated under trl-policy-v3 is still used for training while the trainer is at v7. A rollout that started under v3 must finish under v3. At any moment, vLLM serves the current policy plus the four before it. The trainer keeps max_staleness + 1 adapter versions registered and unloads anything older. Each sync loads the new version before unloading the oldest one, which needs one more slot during the swap. This requires –max-loras 6. With only five, vLLM would silently evict a policy that still has rollouts in flight at every sync.
The system pins vLLM to v0.27.1. vLLM moves fast, and the flags above and the runtime LoRA endpoints are specific to that version. Treat the version as part of the recipe.
Another design option keeps only the latest adapter and always publishes it under the same name. The system did not use this approach because vLLM keys its prefix cache by adapter name. With a single name, KV blocks computed under previous weights would still match after the swap. The prefill would not redone and a rollout could get its prefix from one policy version and its decode from the next. The trainer would have no way to tell, and the ratio would drift away from 1. Versioned names prevent this. A name always means one set of weights, and a cached prefix can never match a newer version.
Dataset choice
The system chose sail/Sanity-Test-R1D-1.5B, the dataset from Defeating the Training-Inference Mismatch via FP16 by Qi et al., 2025. The reproduction code is in sail-sg/Precision-RL.
The authors generated 40 answers for each MATH problem with DeepSeek-R1-Distill-Qwen-1.5B. They kept problems with a success rate between 20% and 80%, yielding 1,460 questions. This dataset is good for RL validation because the questions are neither already solved nor completely hopeless for the model. The model gets a good early signal to train on and improve.
This serves as a robust end-to-end test. If one vLLM replica silently serves the base model under an adapter name, the curve shows it within a few dozen steps. The dataset is small enough to cycle through in less than two hours.
The system uses hyperparameters from the paper’s LoRA scripts in oat/scripts/lora. It uses Qwen/Qwen2.5-Math-1.5B, LoRA rank 1 with alpha 2, a learning rate of 4e-5, 8 samples per prompt, 128 completions per step, a maximum of 3,000 generated tokens and a 4,096-token context.
The trainer
The trainer uses the same vllm/vllm-openai:v0.27.1 image with TRL installed on top. The system ran the PR branch at the time. The same code now ships in TRL v1.14. The training script is a normal AsyncGRPOTrainer script. The only Job-specific values are the output directory and the server URL.
During initialization, TRL calls /server_info. If it finds a lora_config, it uses adapter-only sync. Configurations vLLM cannot serve directly, such as DoRA, modules_to_save, or a rank above –max-lora-rank, fall back to merged-weight sync with a warning. The log should contain Adapter-only vLLM sync enabled.
The proxy
The system needs a proxy between the trainer and the vLLM Jobs for two reasons. Exposed Job ports require an Authorization: Bearer <HF token> header on every request. The proxy adds that header, so TRL does not need to know about it.
The system wants more than one GPU generating. On a single vLLM server, the usual way to get that is –data-parallel-size > 1, but TRL refuses adapter-only sync in that mode. A call to /v1/load_lora_adapter only reaches the DP rank that answers it, so the other ranks would keep serving the base model under the new policy name. On Jobs the question differs because the architecture relies on separate containers rather than data parallelism within a single process.
Speed gains
AsyncGRPO metrics show where the bottleneck sits. Five runs take the same recipe from 3 h 27 min to 53 min for 500 steps.
What it means
Users can now train and serve on separate Hugging Face Jobs without complex cluster networking. The system moves only a few megabytes instead of gigabytes. This reduces the cost and complexity of setting up reinforcement learning workflows.