Current AI models cannot learn from their mistakes without additional training, regardless of whether they come from OpenAI, Anthropic, or open-source alternatives.
Businesses adapting these tools for law or finance usually fine-tune general models. That process often requires hiring internal research teams or expensive consultants known as forward-deployed engineers.
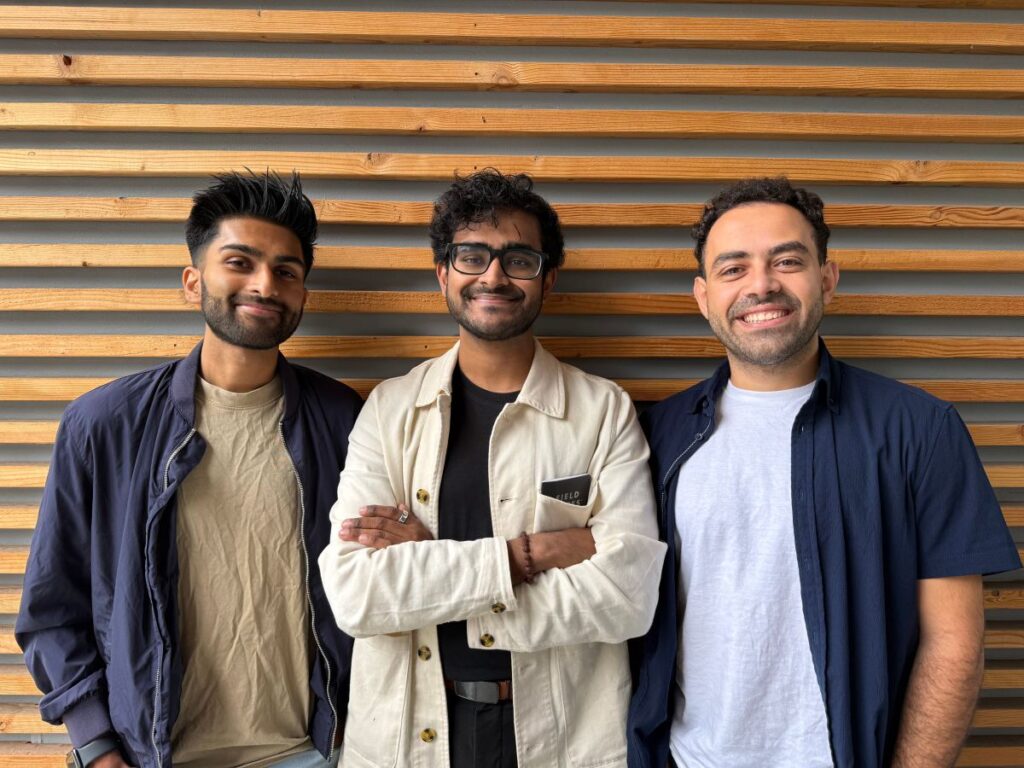
Trajectory, a startup founded by three Stanford classmates with experience at Google DeepMind and Apple, aims to automate that workflow. The company wants AI models to learn from feedback and improve at specialised tasks over time.
The 18-person team announced a $45 million Series A round at a $300 million valuation. Sequoia led the investment, with Nvidia, Bessemer Venture Partners, and Bain Capital Ventures participating.
Trajectory co-founder Ronak Malde compared foundational models to a very smart PhD student starting a new job. “But what the economy values is someone who worked on the job for 30 years,” he told TechCrunch.
The startup uses an approach called continual learning. Companies connect their applications to the Trajectory platform to collect feedback on model performance. The system then retrains the model to help it improve at specialised tasks.
Lawyers, doctors, and other specialists can improve the models themselves, Malde said. That capability could make deploying specialised AI faster and cheaper.
Companies like Harvey and Rogo are already using the platform to post-train open-source models. They help the models perform like experienced lawyers or financial analysts by learning from previous tasks, such as reviewing a specific type of legal contract or valuing a company using a specific methodology.
Trajectory’s other customers include Decagon, Mercor, and Nvidia. The startup is now making its post-training platform publicly available.
“The people using Trajectory decide what good looks like for their organization and can turn that into improvements for their model,” Malde said.
Trajectory’s approach shares some similarities with recursive self-improvement, the idea that AI systems can improve their own capabilities. Co-founder Michael Elabd argues that keeping humans involved in the training process makes the approach safer. He noted that autonomous self-improvement could lead to unintended or even dangerous outcomes.
Thinking Machines Lab, founded by former OpenAI CTO Mira Murati, is a direct competitor. The company also built the fine-tuning platform Tinker. Applied Compute was valued at $3.25 billion last month. Prime Intellect helps companies build and train their own AI agents.
Malde believes the startup’s biggest advantage is its team. He was among the handful of researchers Google DeepMind acqui-hired from Windsurf. Elabd also worked at DeepMind. The third co-founder, Arjun Karanam, previously worked on generative foundation models at Apple.
The startup has also recruited researchers and product designers from OpenAI, Stripe, and Netflix.
Karanam says the interface makes post-training more accessible to non-technical customers.
What it means
Organisations can now train their own AI without building large internal research teams. The platform handles the technical retraining work while domain experts define the quality standards.