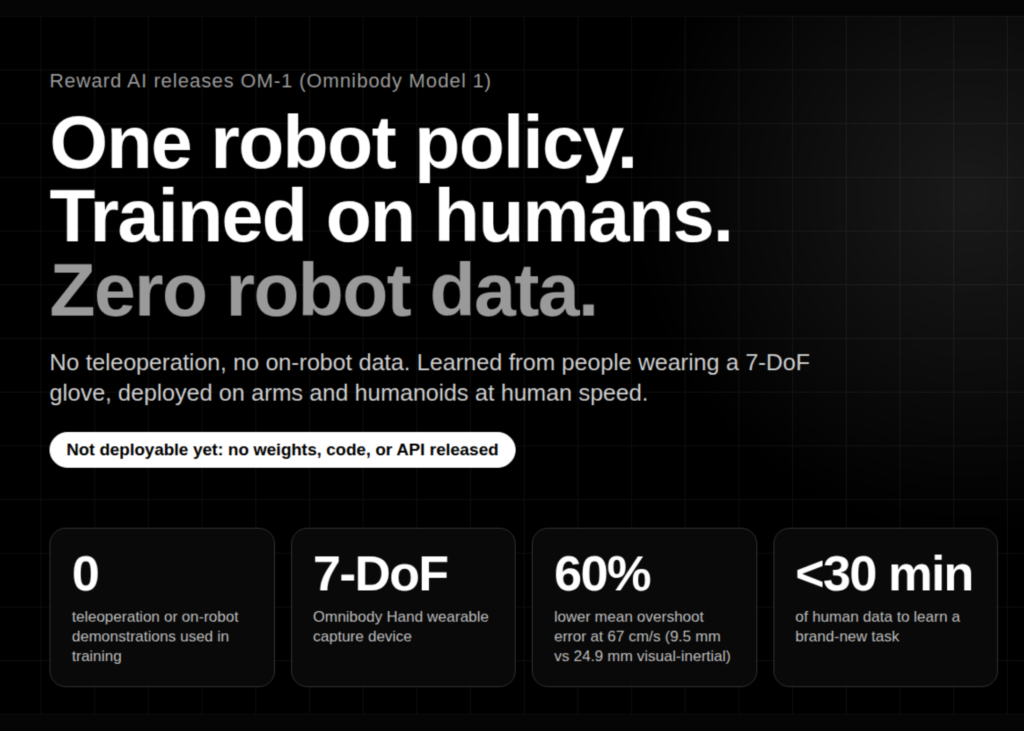
Reward AI has released OM-1, a general-purpose manipulation policy trained exclusively on human demonstrations without any teleoperation or on-robot data. The system operates on industrial arms and humanoids at human speed, adhering to the principle of ‘One Model, One Data Interface, Any Body.’
Developers cannot yet run the policy on their own hardware. No weights, code, datasets, or API access have been released. OM-1 remains an internal tool for the company.
Why Skip Robot Data?
Most robot foundation policies rely on teleoperated or self-collected robot data, which ties the dataset to a specific physical body. Reward AI argues that human-level manipulation does not come from more data or more compute. Citing Anderson’s “More Is Different,” the team states that capture, learning, and control must be designed as one pipeline. This allows demonstrations recorded today to train robot bodies that do not exist yet.
Omnibody Hand: A 7-DoF Wearable
The stack begins with the Omnibody Hand, a wearable device extending the team’s earlier DexCap work on portable motion capture. It is a seven-degree-of-freedom design built around specific functions: choosing contact points, reorienting objects in-hand, and moving between precision and power grasps. It captures thumb-index pinching, thumb and index flexion, and the coupled motion of the middle, ring, and little fingers at the MCP joints.
Ergonomics is treated as a data-quality issue. A device that slips or constrains the wearer produces a compensated grasp. A distal flexion mechanism absorbs differences in finger length, so no per-user adjustment is needed.
One Data Interface: Capturing Contact at Human Speed
One Data Interface turns wearer motion into training data with no staged setup and no supervisor. The design target is conveyor-belt sorting, where a person spots, grasps, and tosses an object in a fraction of a second. To cover the whole interaction, the glove combines high-frequency tactile sensing, proximity sensing for the pre-contact approach, and global-shutter in-hand cameras that hold context through rapid motion.
Hand pose tracking is where Reward AI reports its first quantitative result. Visual-inertial tracking is the common default, but its accuracy at fast reversals is capped by the visual update rate. Reward AI augments it with electromagnetic sensing plus disturbance compensation. Moving both trackers between two mechanical stops at eight speeds from 3 to 67 cm/s, averaged over ten runs each, electromagnetic tracking rose from about 0.4 mm to 9.5 mm of mean overshoot error, while visual-inertial rose from about 2.1 mm to 24.9 mm: a 60% reduction at the highest speed, with a narrower run-to-run spread. Force is recorded along the same trajectory, so demonstrations carry effort as well as path.
OM-1: One Policy, Single-Stage Training
OM-1 learns to generate robot actions directly from human motion rather than routing behavior through an intermediate robot. Because every demonstration arrives in the same format, there is no split between pre-training and post-training: the first demonstration ever recorded and the newest one train a single policy in a single stage.
Inputs are the glove’s multimodal streams: images, tactile signals, inter-finger proximity, and hand pose trajectories. Each modality is processed at its sensor’s native sampling rate rather than downsampled to a common frequency, so high-frequency tactile and motion cues survive alongside lower-frequency vision. Outputs carry motion direction, speed, force, and the timing of events such as grasp initiation. Reward AI says it built a novel architecture for efficient inference, though architectural details and parameter counts are not disclosed.
Control Any Body: An RL Layer on Its Own Clock
Below the policy sits a high-frequency control layer trained with reinforcement learning in simulation to handle velocity- and acceleration-dependent dynamics, external disturbances, and system delays. Where a classical controller pushed off its reference by an unexpected load never recovers, this layer holds the reference and settles back, which is what lets a robot open a fully closed refrigerator door or lift boxes of unknown weight.
The control layer runs on its own clock, continuing while the policy computes the next actions, so inference latency never stalls motion. Because successive predictions may not join smoothly, it optimizes the transition between them online. The same action space covers manipulation and navigation for mobile robots.
Results
Reward AI reports that OM-1 picks up a brand-new task, including challenging dynamics and long horizons, from less than 30 minutes of human data, and attributes this to the integrated stack rather than the policy alone. Its about page states that all published clips run at 1x speed and that the model spans arms, legged humanoids, and wheeled mobile manipulators. No success rates, public-baseline comparisons, or paper have been released, so these claims are demonstration-backed rather than benchmark-backed.