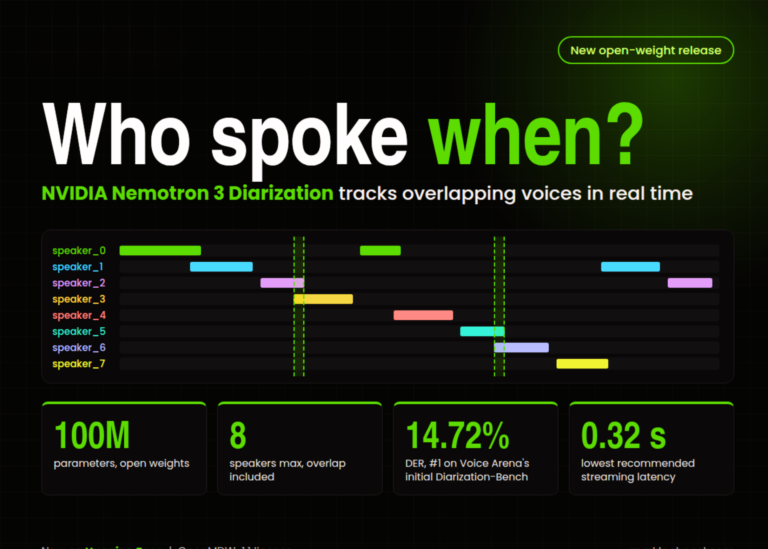
Nvidia has released Nemotron 3 Diarization, a free artificial intelligence model capable of identifying up to eight different speakers within a single audio stream in real time. The system weighs approximately 100 million parameters and operates on both recorded files and live feeds. When combined with a speech recognition engine, it can generate transcripts labelled with anonymous identifiers such as speaker_2. Performance depends heavily on environmental conditions, with heavy background noise or reverberation increasing error rates. The model allows users to adjust the audio buffer between 30.4 and 0.32 seconds, though shorter windows generally reduce accuracy.
The release matters because it achieves the lowest error rate on the Diarization-Bench from VoiceArena, currently standing at 14.72 percent compared to the next best system at 19.3 percent. This benchmark is strict, counting overlapping speech and tiny misalignments at speaker transitions as errors. Nvidia states the new model cuts the error rate by an average of 41 percent across eight test scenarios when using a 1.04-second buffer compared to its predecessor, Streaming Sortformer. The free availability lowers barriers for developers integrating speaker tracking into applications.
- Weights are freely available for commercial and research use.
- Supports up to eight concurrent speakers with overlap detection.
- Outperforms previous Nvidia models by 41 percent in specific buffer configurations.