nemotron-halloween
Building a Haunted House with NVIDIA Nemotron Open Models
Or rather…
Boo! Now Get Off My Lawn!
TL;DR: MonsterHouse is an interactive projection I created for Halloween. He listens to trick-or-treaters, answers in the voice of a grumpy old pirate ship and softens when visitors remember their manners. He is built on the NVIDIA Nemotron Voice Agent with NVIDIA Nemotron ASR, Nemotron 3.5 Bolt E4B 4GB, Magpie TTS Zeroshot and Audio2Face-3D, and he runs on a single workstation.
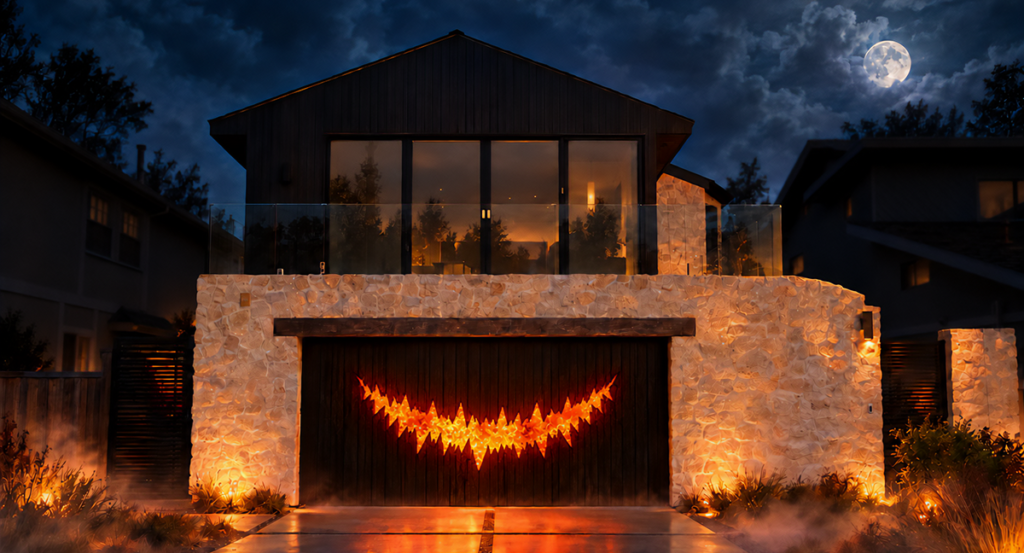
I wanted the kids visiting my house at Halloween to interact in a fun and unique way. The house was going to be in charge and giving out the treats, but more grumpy than scary. Somehow, my solution was to give the garage door a mouth and teach him to complain.
That became MonsterHouse: a grumpy old building with pirate stories, a fiery grin and a suspicious weakness for “please.” NVIDIA Nemotron Voice Agent supplies the conversation foundation. Nemotron Speech does the listening, Bolt E4B is the brain, NVIDIA Magpie TTS Zeroshot is the live voice, and NVIDIA Audio2Face-3D makes the wooden mouth talk.
How Monster House works
- Listening: NVIDIA Nemotron Speech ASR turns visitor speech into text. [CONFIRMED: nemotron-speech-streaming-en-0.6b.q8_0.gguf]
- Thinking: NVIDIA Nemotron 3.5 Bolt E4B 4GB, an open small language model for conversational agents, writes each reply. A LoRA adapter supplies the personality.
- Speaking: NVIDIA Magpie TTS Zeroshot voices each reply from a short reference sample of the character.
- Animating: NVIDIA Audio2Face-3D turns clean speech into mouth animation in Unreal Engine 5.
- Seeing: NVIDIA Nemotron 3 Nano Omni describes costumes, while YOLO and ByteTrack count and track visitors.
- Running it: NVIDIA Nemotron Voice Agent coordinates everything on one workstation with an NVIDIA RTX PRO 6000 Blackwell Max-Q and an NVIDIA RTX PRO 4000 Blackwell.
A grin full of splinters
The mouth came first. I imagined the wooden garage door boards splitting into jagged lips, with the burning flames of hell illuminating the driveway from beyond whenever he opened his cursed mouth. He needed to look ancient, expressive and mildly offended by the existence of visitors.
A few expressions from a house with plenty to say.
Creating a custom animation rig was one of the more labor intensive parts of the build. After bashing it into submission, I could export the facial expression shapes that Audio2Face-3D could later animate. The character SkelMesh was built in Autodesk Maya then exported into Unreal Engine where virtual fire and effects were added behind the door. With no eyes, no eyebrows and no blinking, he’s a surprisingly economical monster.
While all the nonsense of building the character was going on, NVIDIA built the Nemotron Voice Agent. What was supposed to be the hard part of the build now became rather fun, iterative and easy. I had a foundation for listening, conversation and speech right out of the box. The house already had a mouth. Now he could finally find something to complain about.
Teaching bad manners
The house needed a past as cantankerous as its personality so I devised a backstory that the house had been built from the timbers of a sunken pirate ship, haunted by its stormy past. The nautical complaints now had a reason. This was the ship, reincarnated as real estate and not entirely pleased about it.
The performance needed a guide, a path to follow from greeting to goodbye while providing treats along the way. First, the house would brush visitors off with remarks like “I’m busy grumbling, go bother the neighbors!” But persistence would wear him down. A “Please” could break through immediately, and “thank you” earned a warm farewell. Once a visitor won him over, I wanted him to stay won over. Nobody wants to negotiate with the same garage door twice.
Here is where the Voice Agent really shines. You can choose any LLM you like. Because I wanted the system to be off-grid and completely self-contained, I had a memory and compute budget.
The character needs more than a prompt that says “be grumpy.” It had to follow a master conversation flow, respond to what visitors actually said, track encounter state, and leave enough compute for the rest of the pipeline.
After testing more than a dozen models, I landed on Bolt E4B to supply the live dialogue. It is an open small language model purpose-built for local conversational agents and interactive characters, which is a fair description of a talking garage door. I use the 4-bit quantized release (the “4GB” in its name) as the default response model, with the BF16 checkpoint available for comparison.
If it’s not obvious by now, I work at NVIDIA and due to this I was able to test Bolt E4B before its public release and found it to be a solid choice, with a smaller footprint than other frontrunners- Qwen3 30B-A3B and Qwen 3.6 35B-A3B.
It works inside the Nemotron Voice Agent pipeline, turning what visitors say into the next suitably reluctant reply.
Bolt provides the conversational foundation. My prompts, application logic and LoRA adapter trained on thousands of reviewed example conversations shape it into this particular stubborn ship.
Creating a dataset of over 5000 multi-turn conversations meant I could train LoRAs for each model I felt good enough to be an option. Some took about an hour to train, some took a couple. A local agent ran everything and benchmarked the results. That agent and a very large LLM created and judged the dataset to begin with. This happened at night or while I was doing the day job.
With the LoRA in place I check the replies for continuity, timing and tone, benchmark models and adapters for quality, repetition and speed, and then listen to the performance. The house should give in eventually, without turning into a cheerful concierge. A little resistance is part of the charm. An endless argument with a garage door is not.
A voice worth waiting for
Two shortcuts, two outputs. Authored text skips fresh dialogue generation, and saved audio skips synthesis. Clean speech drives the animation separately from the audience effects.
A haunted house loses authority if he takes too long to complain. The pipeline releases speakable text before an entire answer is finished, so the house can start talking while the rest of the sentence is still on its way. Prepared greetings and candy jokes cover familiar encounters: the text bank saves language-model work, and cached recordings save speech synthesis. Even an ancient grump benefits from rehearsing.
median end-of-speech-to-audio with Bolt Q4 & TTS = 1.70 seconds median end-of-speech-to-audio cached responses = 0.72 seconds (note: speech-end detection currently waits for 300 ms of silence )NVIDIA Magpie TTS Zeroshot turns text into the Queen’s English. Its zero-shot voice conditioning uses a short reference sample instead of a trained voice; mine supplies the grumpy pirate character. The house has seven moods, from grumpy and menacing to amused and delighted, and emotion tags dictated by the prompt template and provided by the LLM choose how each line is delivered. Since each emotion requires a different 3-10 second voice sample I added a “Sample your Voice” block on the UI’s tool tab. I could then read and record a sample line of text in my best happy pirate or angry pirate voice. When it’s “Go” time, Bolt E4B decides what to say, and Magpie turns that text into speech with the proper delight or despair.
Next down the pipe is Audio2Face-3D and the 3d character scene I created in Epic’s Unreal Engine. The default model weights work best with a clean neutral male or female voice, not too deep, not too high (choose the appropriate gendered model for your use case). I wanted the house to have a very deep and demonic voice with echo and chamber. In this case, since my voice samples don’t have that theatrical heft, it’s actually a benefit. Audio2Face-3D gets clean speech from the samples and a second audio stream adds adjustable real-time vocal effects that play out the speakers.
To keep everything running smoothly, I split the work to a pair of GPUs: the language and voice model pipeline runs on an NVIDIA RTX PRO 6000 Blackwell Max-Q, and Unreal Engine graphics with Audio2Face-3D runs on an NVIDIA RTX PRO 4000 Blackwell. Memory isn’t the issue, compute is. I want to keep animation at a consistent frame rate regardless of what processing the agent pipeline is doing.
Voice, animation and effects have to land together. A convincing monster needs more than a fast answer; it needs to sound as though the complaint belongs to the building. In my case, he does. Tweaks to sync audio delivery are available. I’ve found I could set them and forget them. (100ms compensates for the Audio2Face-3D buffering)
The monster has a control desk
Somewhere along the way, “make the house talk” required an interface full of controls. I can audition cached lines, adjust the opening mood, follow the conversation, change the voice treatment and tune the mouth animation. Tabs cover conversations, model selection, recordings, prompts, performance monitoring and camera feeds, and a soundboard and custom dialogue field let me put words in his mouth. There are also model-loading controls and an Unreal Engine connection indicator, because sometimes the monster is not sulking. He is disconnected.
The MonsterHouse control desk, with the soundboard, custom lines, opening mood and conversation flow.
The fire and glow have joined the act. Editable rules tie visual cues to delivery: live cues begin with speech, while recorded performances can follow a saved timeline. I can direct a change of mood without rebuilding the scene.
Live mode runs the trick-or-treat character. Demo mode persuades The house to explain himself. Microphone mode lets me speak through the house directly, bypassing recognition, dialogue generation and speech synthesis. My clean voice drives the mouth; the audience hears the treated version. The house considers this possession. I consider it a useful fallback.
The next knock at the door
NVIDIA Nemotron 3 Nano Omni is a VLM that gives the house visual context. As an optional observer, it interprets camera images and describes visible costumes so the character has something specific to react to. Not looking to reinvent every wheel, I chose the popular object detection and tracking models YOLO and Byte
Source Read original →