Apple researchers have built a system that automatically translates decades of NVIDIA CUDA kernel expertise into high-performance code for Apple Silicon, achieving near-expert speed on local machines.
Computing hardware is diversifying rapidly. GPUs from different vendors now offer distinct architectures, each tuned for specific AI tasks. While AI coding tools can generate code quickly, they struggle with the low-level work of writing efficient GPU kernels. These kernels are the programs that run inside the processor, and crafting them correctly requires years of experience. Transferring a kernel from one vendor to another often forces engineers to rediscover optimizations from scratch.
The CUDA ecosystem holds a massive advantage here. It contains thousands of hours of hand-tuned code for operations like attention mechanisms and state space models. Newer platforms, such as Apple Silicon, are growing fast but lack this depth. The team at Berkeley AI Research asked if this accumulated knowledge could be transferred automatically.
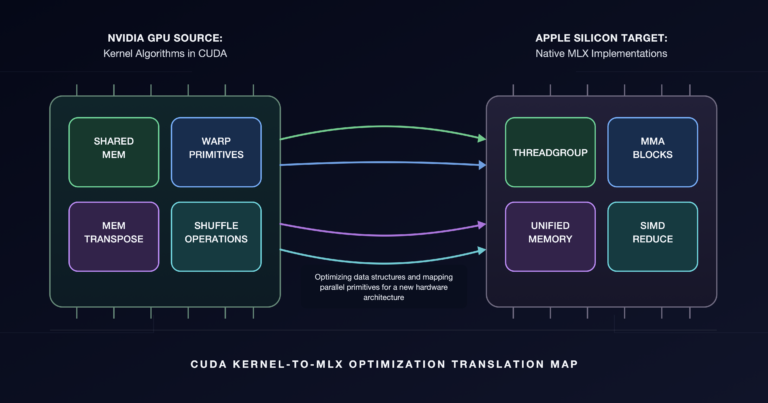
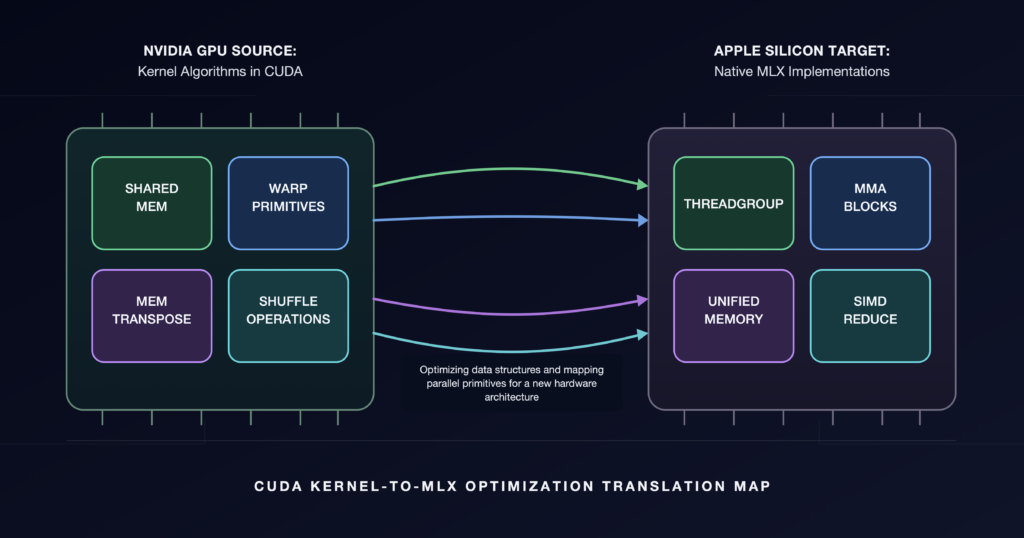
They extended K-Search, an evolutionary kernel search framework introduced by Shiyi Cao at Berkeley Sky Lab. This tool uses AI to optimise GPU kernels. The new version includes a backend for MLX, Apple’s machine-learning framework for its own chips. It features a structured translation layer that adapts existing CUDA kernels into high-quality GPU kernels for Apple Silicon without rebuilding them from the ground up.
The results show near-expert performance on Apple Silicon. The new kernels reached 0.97x speedup compared to the native MLX Attention kernel. On the Mamba SSM kernel, the team saw up to a 20x prefill speedup over the community mlx-lm implementation. The report details how much of this gain comes specifically from the translation layer.
Why MLX
Apple’s MLX framework has seen rapid adoption since late 2023. With Apple Silicon present in hundreds of millions of MacBooks and Mac Studios, MLX enables local AI inference without cloud costs. Its unified memory architecture is particularly attractive for mid-sized models ranging from 7B to 70B parameters on M series chips.
Despite this momentum, a significant gap remains. Many performance-critical kernels that are standard in the NVIDIA ecosystem are absent or naive in MLX without specific hardware tuning. These include paged attention, optimised SSM scan kernels, and fused MoE routing. MLX runs models correctly but often leaves significant performance on the table.
This gap is what motivates the rest of this post.
What is K-Search
K-Search is an evolutionary kernel optimization framework originally developed by Shiyi Cao at UC Berkeley Sky Lab. Given a naive kernel and a hardware specification, it runs an iterative optimization loop. An LLM reasons about which optimizations to try next, a code-writing model generates candidate kernels, and those candidates are compiled and benchmarked on real hardware.
Measurements feed back into the search, which keeps refining, pursuing promising directions and dropping dead ends until performance converges.
Search is grounded by a Spec: a domain-specific document encoding hardware rules, optimization patterns, and mathematical constraints. This keeps generated code from hallucinating invalid primitives and ensures candidates will actually compile and run efficiently.
In the runs, a single model (Gemini 3.5 Pro Preview) plays both roles. It maintains the reasoning state and writes the kernels. The reasoning half is prompted as a “GPU kernel performance engineer” and asked to work through a fixed analysis before proposing anything. It classifies the kernel, rewrites the reference computation in canonical form, maps out data layout and access patterns, and hypothesizes the likely bottleneck in each runtime regime. Only then does it emit candidate optimizations, each as a single change implementable in one iteration.
The team calls the persistent reasoning state a world model. Rather than a flat list of things to try, it is a decision tree. Each root to leaf path composes a full optimization plan, and sibling branches are competing alternatives. Every node is scored with an overall rating between 0 and 10, a confidence score between 0 and 1, and per-node impacts on memory bandwidth, register pressure, and compute fit. This allows the search to rank partial plans and expand the most promising ones.
The tree persists and grows across rounds. Refining an idea adds a child node rather than overwriting its parent. If the best score fails to improve for a few rounds, a stagnation window triggers the search to back off and explore an alternative branch.
Example K-Search world-model node: A candidate optimization records a concrete action, estimated hardware impacts, an overall priority rating, and the model’s confidence.
The original K-Search paper evaluated this search strategy on CUDA kernels from FlashInfer. Across GQA decode, MLA decode, MLA prefill, and MoE, K-Search improved more consistently than OpenEvolve and ShinkaEvolve over the same 120-iteration budget. These results establish the search framework the team builds on here. The remainder of this post asks whether its optimization knowledge can transfer beyond CUDA.
Building an MLX backend
To bring K-Search to Apple Silicon, the team first built a native MLX backend. They implemented a full MLX-specific task adapter for K-Search, including an MLX task backend in k_search/tasks/ handling kernel compilation and execution on Apple Silicon via MLX’s Metal/C++ APIs.