AI News
Stay current with the latest artificial intelligence news. AI Maestro covers breaking stories, product launches, policy changes, and industry developments from the world of AI — curated and rewritten daily from the most trusted sources in tech.
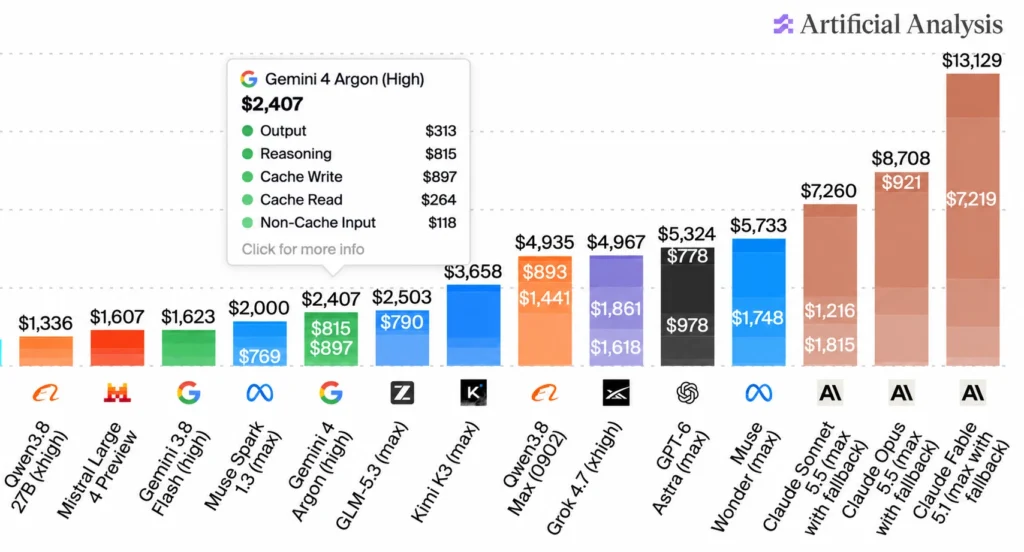
llm-gemini 0.35
Release: llm-gemini 0.35 I added support to llm-gemini for the new Gemini 4 Argon model, made available today via the Gemini API…
Top stories
Tue 12 May 10 stories
-
 AI News
AI May Reshape Institutions More Than It Replaces Jobs
AI May Reshape Institutions More Than It Replaces Jobs I believe that the next big AI debate won’t…
12 May 2026 -
AI News
How do I use MTP?
**Editorial Brief** The post titled “How do I use MTP?” on r/LocalLLaMA discusses a user’s experience attempting to…
12 May 2026 -
AI News
Drastically improve prompt processing speed for –n-cpu-moe partially offloaded models
Bigger ubatch made gpt-oss-120b prompt processing much faster on my RTX 3090 I was tuning gpt-oss-120b-F16.gguf with llama.cpp…
12 May 2026 -
AI News
Qwen3.6 27b q5_k_M MTP – 256k context – 5090
**Editorial Brief** Qwen3.6, a large language model with 27B parameters and MTP (Memory-Tied Pretraining) enabled for a context…
12 May 2026 -
AI News
Drastically improve prompt processing speed for –n-cpu-moe partially offloaded models
Drastically improve prompt processing speed for –n-cpu-moe partially offloaded models I was tuning gpt-oss-120b-F16.gguf with llama.cpp on a…
12 May 2026 -
AI News
Stop wasting electricity
**Editorial Brief** A Reddit post titled “Stop wasting electricity” suggests lowering the power limit on an RTX 4090…
12 May 2026 -
AI Music
Cache-testing software for LLM-provider-style tiered ephemeral caches? [D]
“`html Cache-testing software for LLM-provider-style tiered caches Introduction I’m seeking a cache simulator or benchmark suite suitable for…
12 May 2026 -
AI News
Models and Quants quality test results – the chessboard svg (Qwen3.6 27B/35B-A3B/Zaya1)
According to this. I run several more tests to cover more models and quants. https://www.reddit.com/r/LocalLLaMA/comments/1t53dhp/quality_comparison_between_qwen_36_27b/ Qwen3.6 35B-A3B MLX…
12 May 2026 -
AI News
Drastically improve prompt processing speed for –n-cpu-moe partially offloaded models
“`html Drastically improve prompt processing speed for –n-cpu-moe partially offloaded models Drastically improve prompt processing speed for –n-cpu-moe…
12 May 2026 -
AI News
AI turning aggressive generalists into fucking institutions
AI Turning Aggressive Generalists into Fucking Institutions Brighton, I’m here to share a perspective on what’s happening with…
12 May 2026