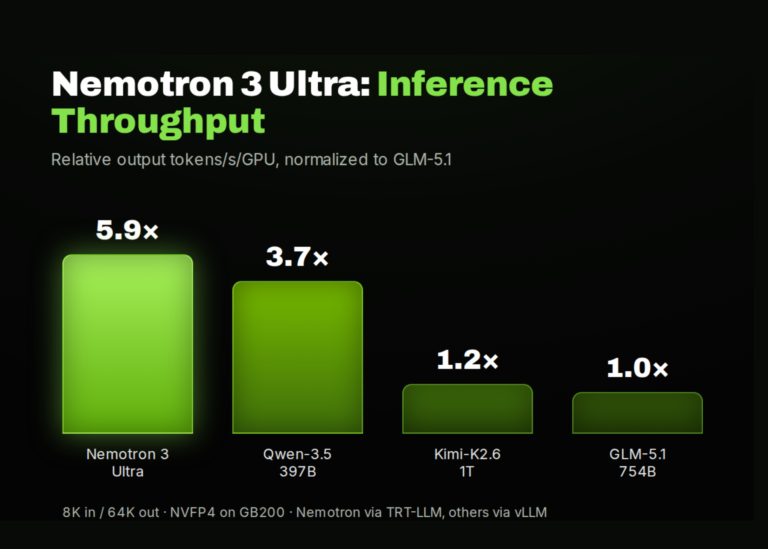
Box announced at its developer conference that it is integrating Nvidia’s Nemotron embedding system into its core product suite. The new feature, called Box Content Retrieval, enables automated agents to query company data more effectively by relying on embedded metadata generated by Nemotron. Box states this integration will result in faster, more accurate, and cheaper queries. Nvidia’s VP of generative AI software, Kari Briski, told TechCrunch she expects responses to be four times faster with 20% fewer errors and 90% fewer tokens used. The system will be available to Enterprise Advance customers early next year.
The feature implements Nvidia’s Nemotron Embed project, which provides open-weight models to improve automated retrieval systems. Major labs have often overlooked such models, which use large language models to pre-process data for better agent interaction. The sector has been a focus for Nvidia’s open-source model project, with its recent Nemotron release in July topping the RTEB benchmark. The system is most useful when paired with active agents, such as lawyers finding relevant clauses or precedents. Because Nemotron’s embeddings map underlying concepts beyond simple keywords, a search tool can surface related legal themes even when different wording is used. While the Nemotron models are freely available, the system relies heavily on Box’s pre-existing metadata and permission controls.
* Available to Enterprise Advance customers only
* Rolling out early next year
* Combines five different technologies into one API