AI News
Stay current with the latest artificial intelligence news. AI Maestro covers breaking stories, product launches, policy changes, and industry developments from the world of AI — curated and rewritten daily from the most trusted sources in tech.
llm-gemini 0.35
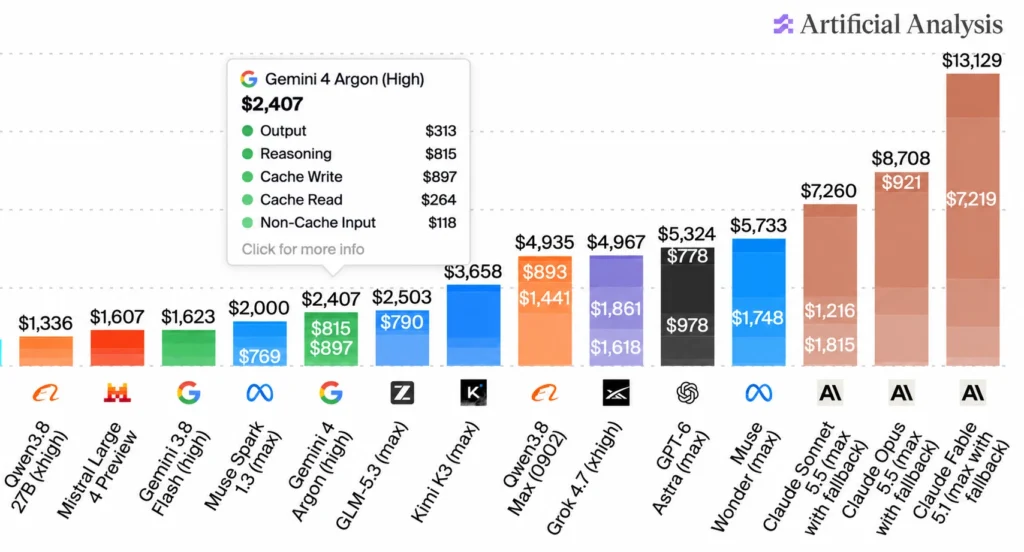
Release: llm-gemini 0.35 I added support to llm-gemini for the new Gemini 4 Argon model, made available today via the Gemini API…
Top stories
Tue 12 May 10 stories
-
 AI News
RTX 5060Ti 16GB or RTX 3080 20GB?
**Editorial Brief** The question of whether to upgrade from an RTX 5060Ti with 16GB VRAM to either a…
12 May 2026 -
AI News
Drastically improve prompt processing speed for –n-cpu-moe partially offloaded models
Drastically improve prompt processing speed for –n-cpu-moe partially offloaded models I was tuning gpt-oss-120b-F16.gguf with llama.cpp on a…
12 May 2026 -
AI News
I realized ChatGPT has become a record of how I avoid thinking
**Content:** I recently exported my ChatGPT history and noticed an uncomfortable pattern. Instead of seeking to understand the…
12 May 2026 -
AI News
Vulkan or CPU llama cpp backend for local llm for coding/code assist
Vulkan or CPU llama cpp backend for local llm for coding/code assist Hi all, I recently started a…
12 May 2026 -
AI News
Drastically improve prompt processing speed for –n-cpu-moe partially offloaded models
Drastically improve prompt processing speed for –n-cpu-moe partially offloaded models I was tuning gpt-oss-120b-F16.gguf with llama.cpp on a…
12 May 2026 -
AI News
Attention Drift: What Autoregressive Speculative Decoding Models Learn
“`html A new phenomenon called “attention drift” has been identified in speculative decoding models, where the drafter’s attention…
12 May 2026 -
AI News
I made an agentic “Daily Brief” for my kids with a receipt printer
**Editorial Brief** A British Reddit user has developed a creative daily briefing system for their children using an…
12 May 2026 -
AI News
New Qwen3.6 27b Autoround Quant (int4) Best Recipe
“`html A new best recipe for the Qwen model has been shared by a user on Reddit. The…
12 May 2026 -
AI News
Drastically improve prompt processing speed for –n-cpu-moe partially offloaded models
Drastically improve prompt processing speed for –n-cpu-moe partially offloaded models Drastically improve prompt processing speed for –n-cpu-moe partially…
12 May 2026 -
AI News
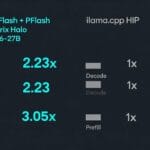
Luce DFlash + PFlash on AMD Strix Halo: Qwen3.6-27B at 2.23x decode and 3.05x prefill vs llama.cpp HIP
Luce DFlash + PFlash on AMD Strix Halo: Qwen3.6-27B at 2.23x decode and 3.05x prefill vs llama.cpp HIP…
12 May 2026